The context→answer mapping is inherited from pretraining
Highlight text on any card (body, plan, or an event) to anchor a comment, or leave a whole-task comment here. Mention @claude to summon a reply.
No comments yet.
Motivation
- An earlier experiment found a linear mapping from a single context vector to the mean answer vector in the instruct model (R² ~0.7, #779)
- I wanted to characterize where that mapping comes from and what carries it:
- does it exist in the pretrained-only model, and what does post-training change?
- does it require the chat-template tokens?
- is it a general character→dialogue mechanism (fiction), or generic next-span prediction, or something chat-specific?
- which part of the input carries it, and how far ahead does it reach?
TLDR
- The mapping already exists almost entirely in the pretrained base model:
- held-out R² 0.588 for base vs 0.673 for instruct at the shared best layer ~87% of instruct prediction strength
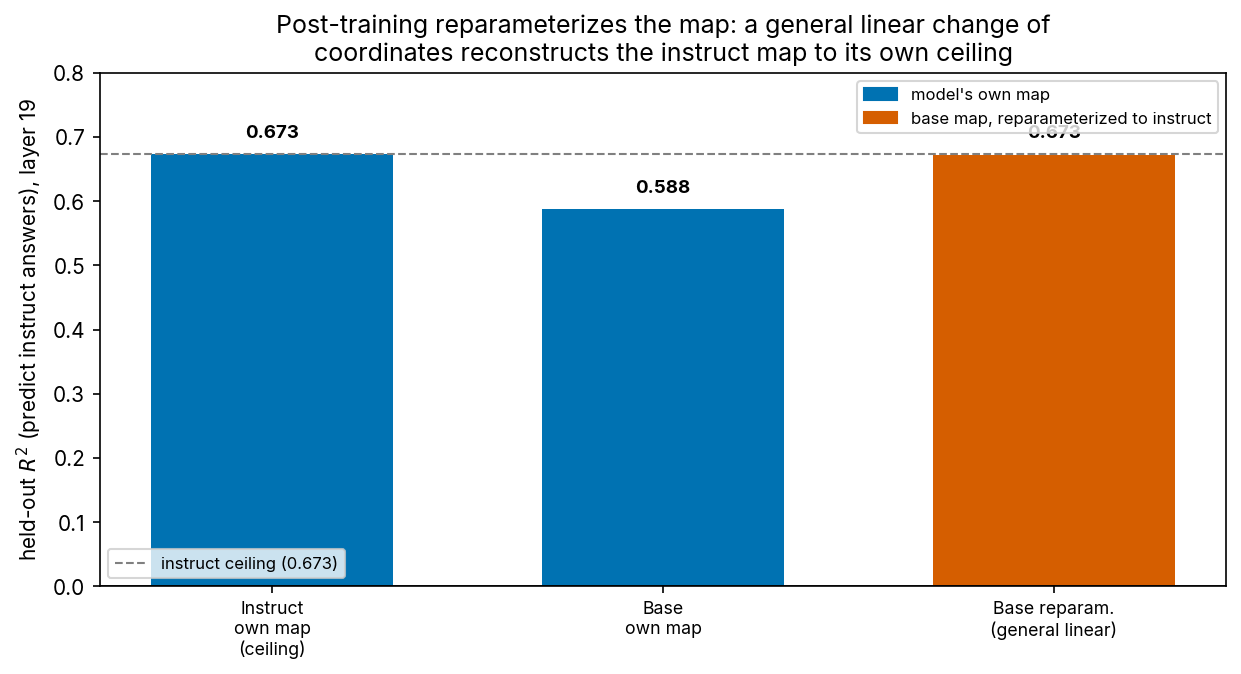
- Post-training reparameterizes the existing mapping by a general linear map
- the base map, run through a fitted general-linear change of coordinates, has as much predictive power as the instruct map on instruct model text
- The mapping holds up without chat-template tokens (in both base and instruct model):
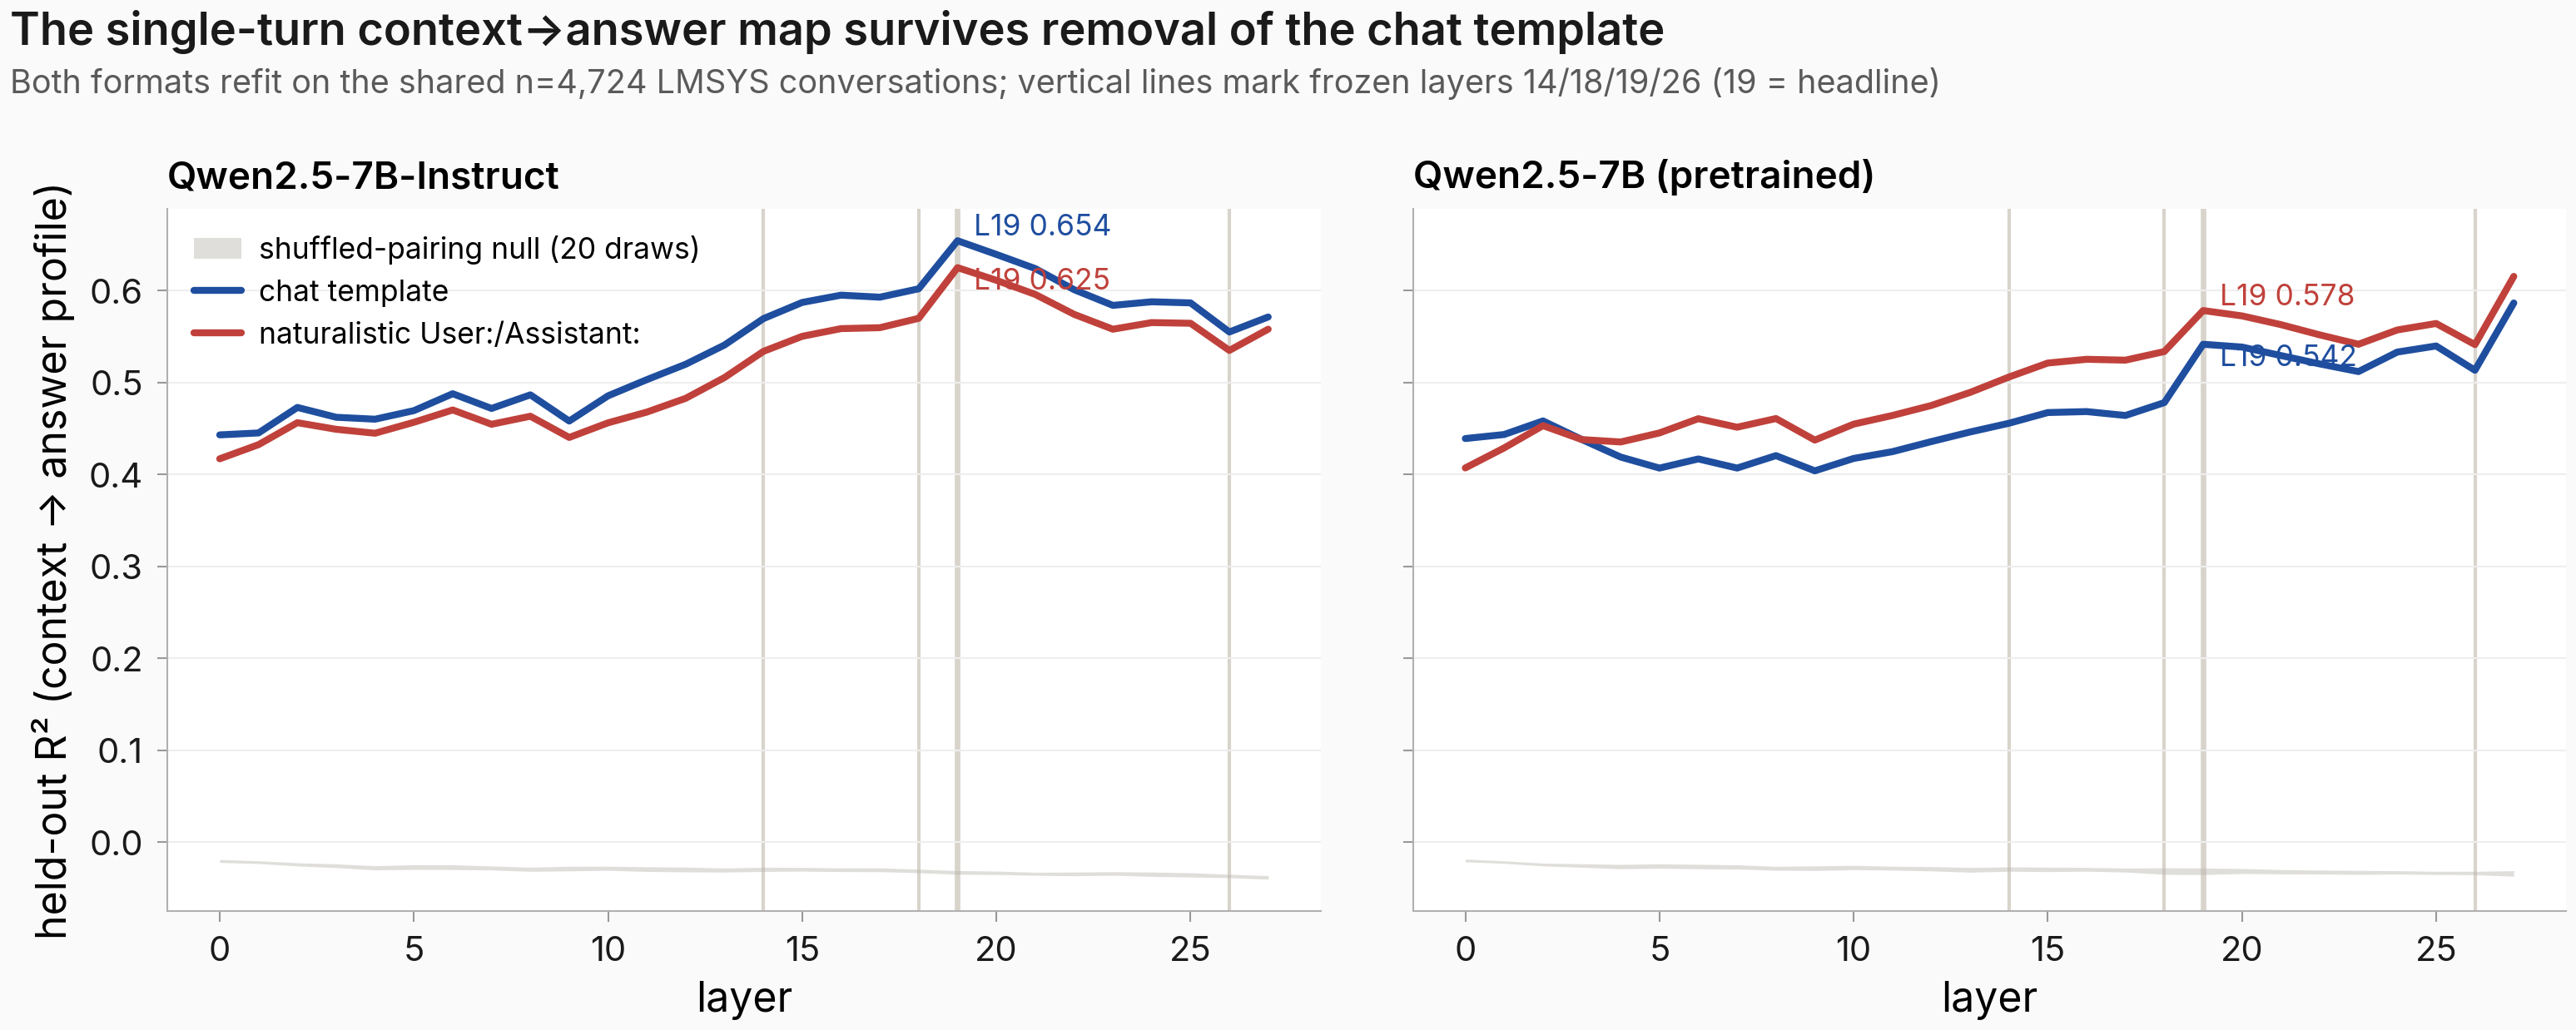
- refit on the same single-turn conversations rendered as plain "User:/Assistant:" text: instruct (vs chat), base (vs chat) at layer 19
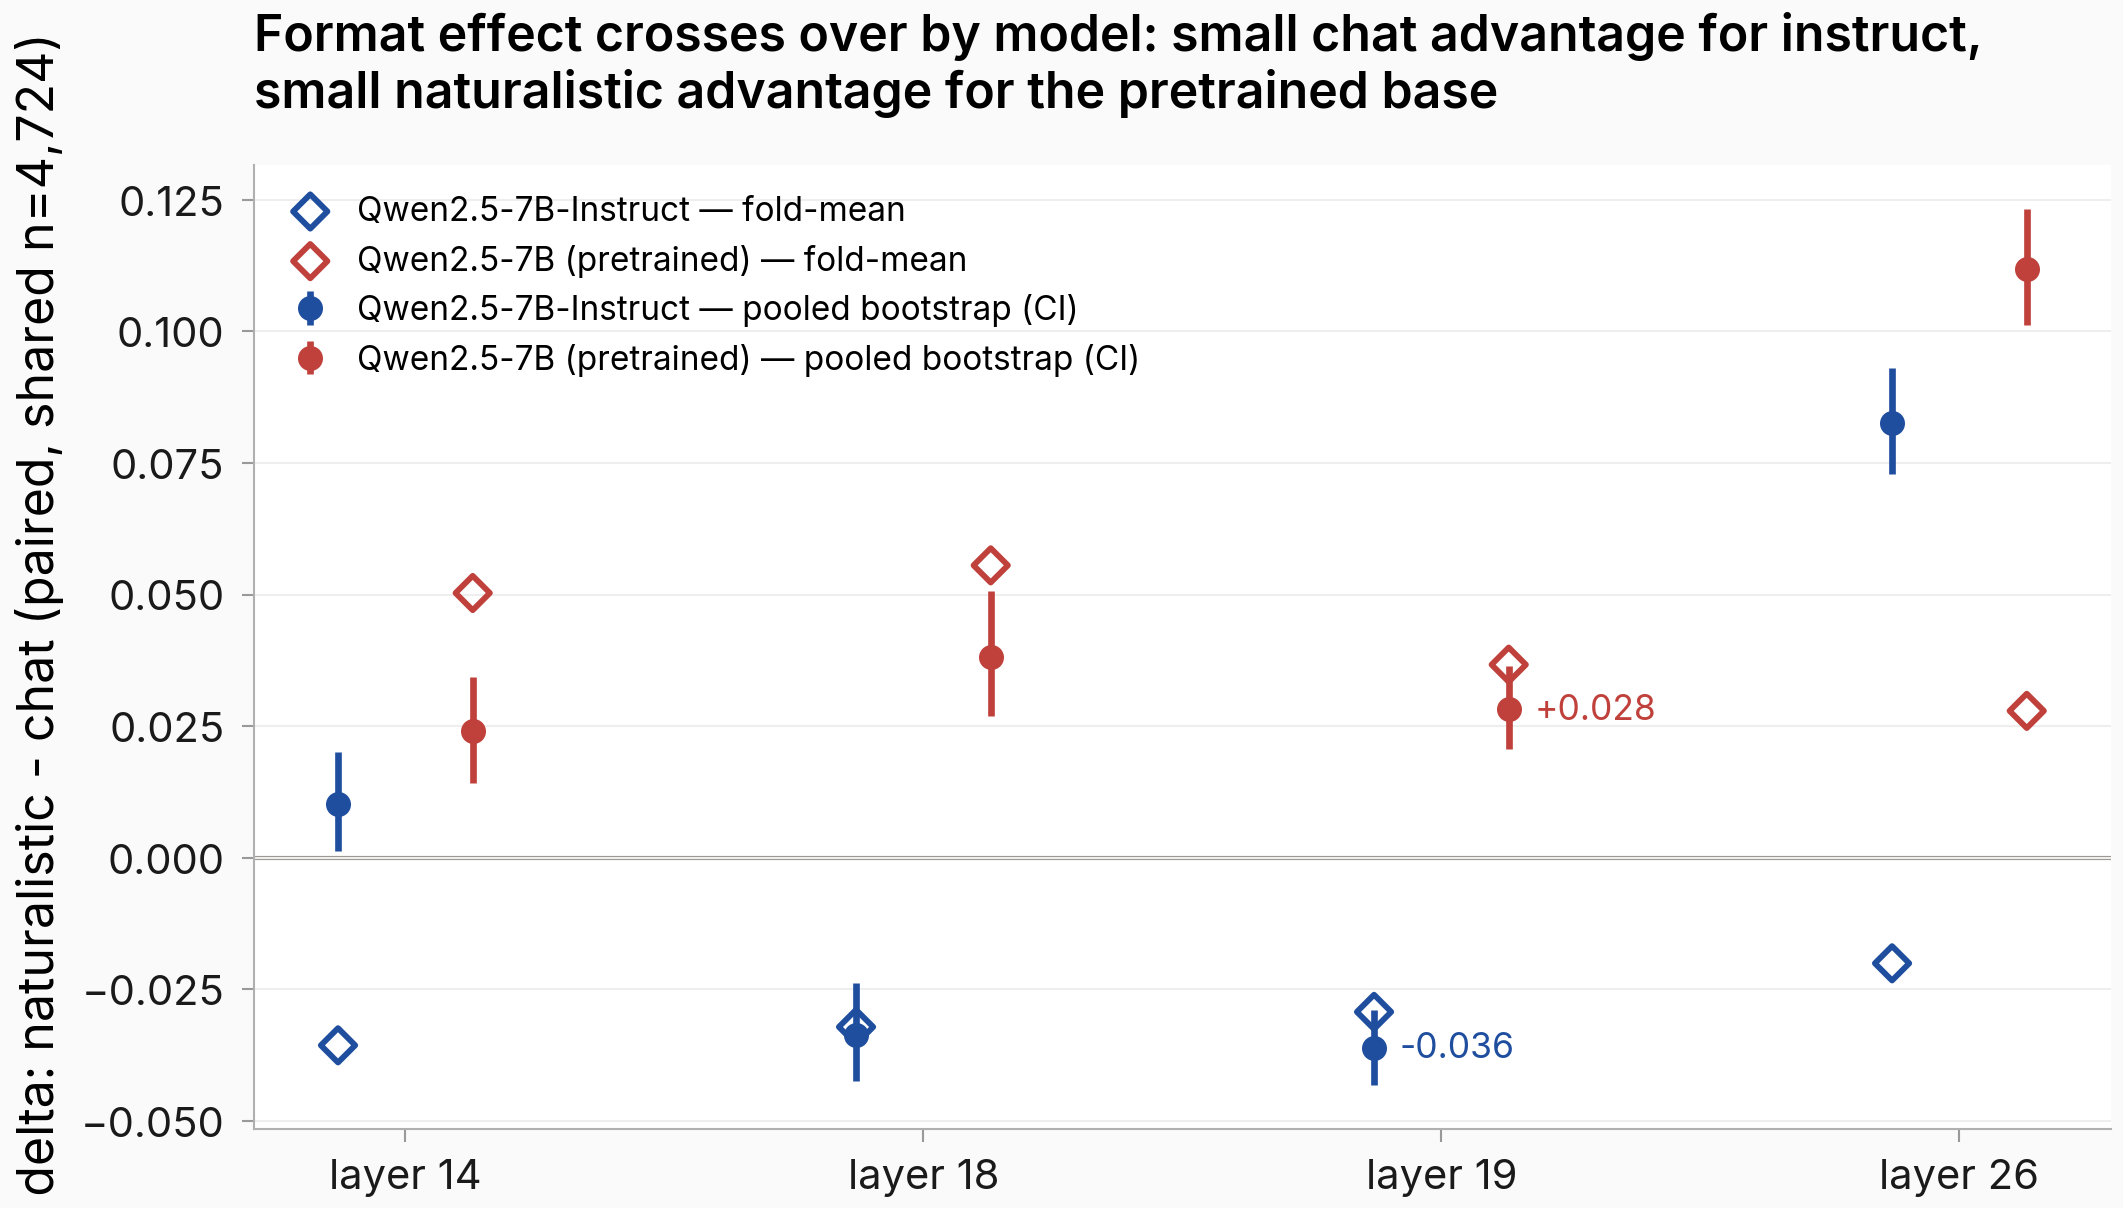
- small format×model crossover, both sides distinguishable from zero under a paired bootstrap: removing the template costs instruct ~0.03 R² and gains the base ~0.04
- without the template the base/instruct strength ratio rises to ~93% (from ~83% chat at matched n)
- The user turn is only weakly predictable — ~2.5× below the assistant on the same rig (corrected 2026-08-19, per the 2026-07-25 selector-audit settle battery):
- the earlier bolded read "the user's next turn is linearly unpredictable (ridge R² negative)" was an unguarded-GCV estimator artifact at n_tr < D: under a guarded selector (GCV_DOF_CAP=0.9) all four user cells flip from −1.43…−1.65 to held-out R² +0.19…+0.25, matching the banked MLP band (0.19–0.23) — the user ≪ assistant role asymmetry survives; the linear-vs-nonlinear gap does not
- The mapping does NOT hold up for generic stories (off-policy or on-policy):
- re-training the mapping on generic stories gets for both on-policy generated stories and off-policy stories taken from the internet
- The mapping is not just generic next-span prediction:
- training a mapping from punctuation tokens to the span of text before the next punctuation token in generic text gives in the base/instruct models
- At n≈5,000 per turn the per-turn mapping is flat at near single-turn strength at EVERY depth (turns 1–16):
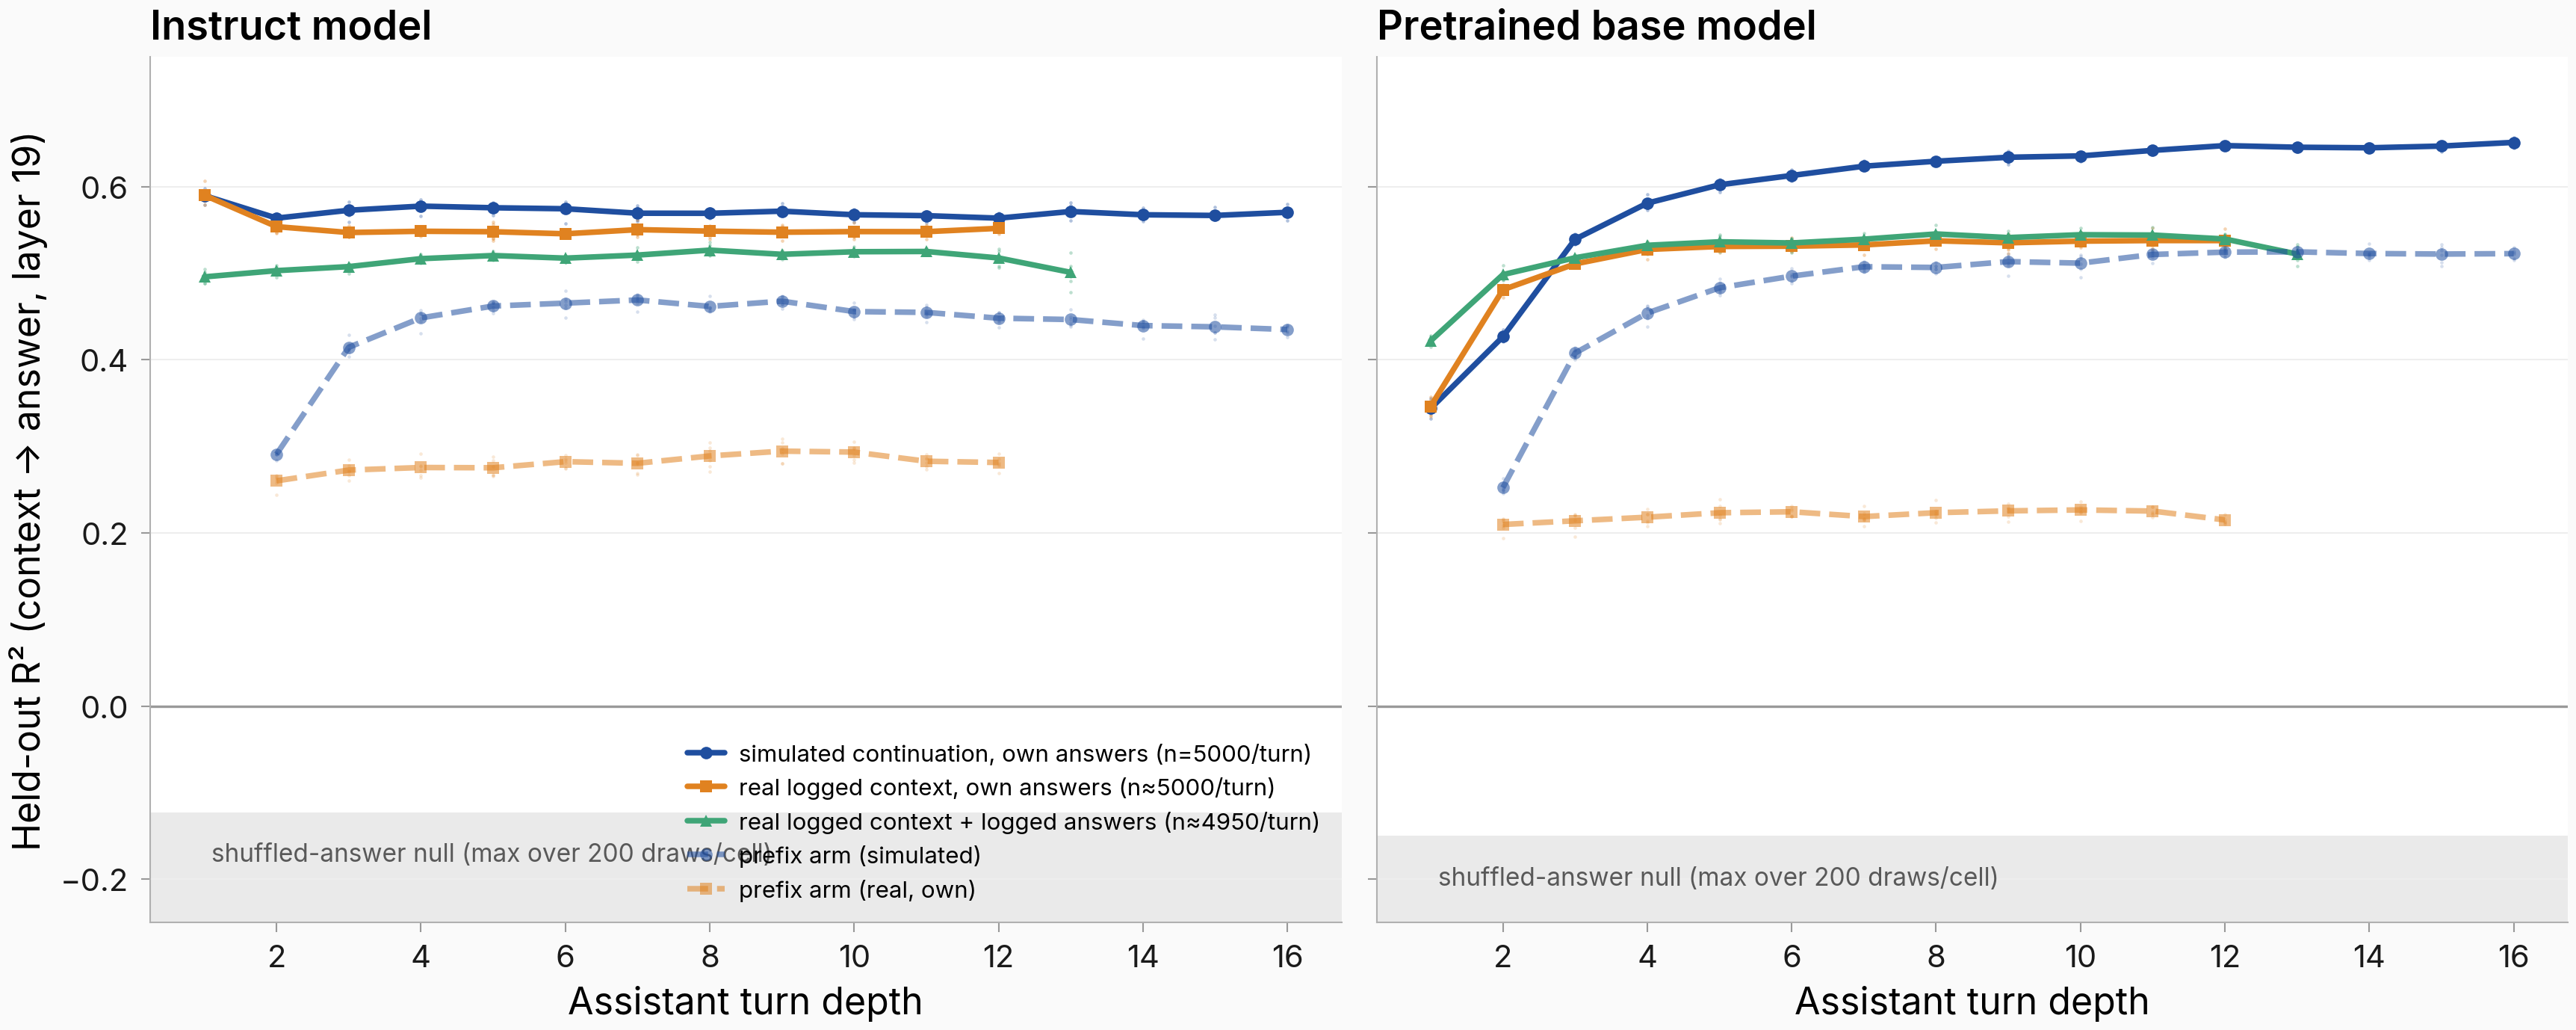
- instruct 0.55–0.59 at every turn (~81–88% of the 0.673 single-turn anchor) — the earlier "half strength, decaying with depth" read (Result 6) was a small-n artifact, and the prefix (pre-query) state alone carries ≈half of the read from turn 2 on (47–50% real instruct, 40–44% pretrained)
- from turn ~3 on it is ONE shared map (cross-turn transfer keeps ~95% of own-turn ); the turn-1 map is genuinely different (its transfer goes negative beyond ~8 turns)
- The base model catches up with depth:
- turn 1: base at 58% of instruct ( 0.34 vs 0.59); it matches instruct by turn ~4 and reaches 0.65 by turn 16 in the simulated arm — post-training's advantage on this map is a turn-1 effect; a few turns of in-context conversation substitute for it
- The turn-1 context keeps predicting later answers linearly, decaying smoothly with horizon:
- ridge 0.29 predicting the turn-2 answer, decaying to 0.04 at turn 16 (instruct, n=5,000, above the shuffled-pairing null throughout); the earlier "linear breaks at two turns, nonlinear holds" read (Result 5) does not survive power — the matched MLP probe never beats ridge
Methodology
- Models: Qwen2.5-7B (pretrained base) vs Qwen2.5-7B-Instruct
- : activation at the end of the context (taken at best layer from prior experiments)
- : the mean activation over the answer span (taken at best layer from prior experiments)
- Estimator: ridge regression for linear, MLP for nonlinear
- Metric: held-out R² (variance-weighted over the 3,584 dims
- Turn-dynamics round (Results 7–9): fixed panel of 5,000 real logged conversations with ≥12 assistant turns (WildChat+LMSYS, K_real=12) + the same openers extended to 16 assistant turns by a simulated user (claude-haiku-4-5 user turns, one persona brief per conversation; the subject model's own answers accumulate on-policy, temperature 1.0, one draw); lambda-grid ridge, conversation-grouped 6-fold CV, layer-19 headline (layers 14/18 committed), 200-draw shuffled-answer null per cell; parity gate: refitting the exact round-10 497-conversation panel reproduces round-10's per-turn values (e.g. turn 1: 0.2121 vs 0.2117; 21 gating cells pass, 9 non-gating under the rank-space degenerate-CI carve-out, 0 fail, both models)
Results:
Result 1: The mapping already exists almost entirely in the pretrained base model
I first wanted to see if the mapping already exists in the base model
Methodology (this result):
- 5000 LMSYS user turns
- answers generated either by base model or instruct model
- 5-fold cross validation across 4000 samples (chat templated data in both base and instruct model)
- compute mapping in base model
- compute mapping in instruct model
- Compare for both at all layers
- Baseline = shuffled context/answer pairings
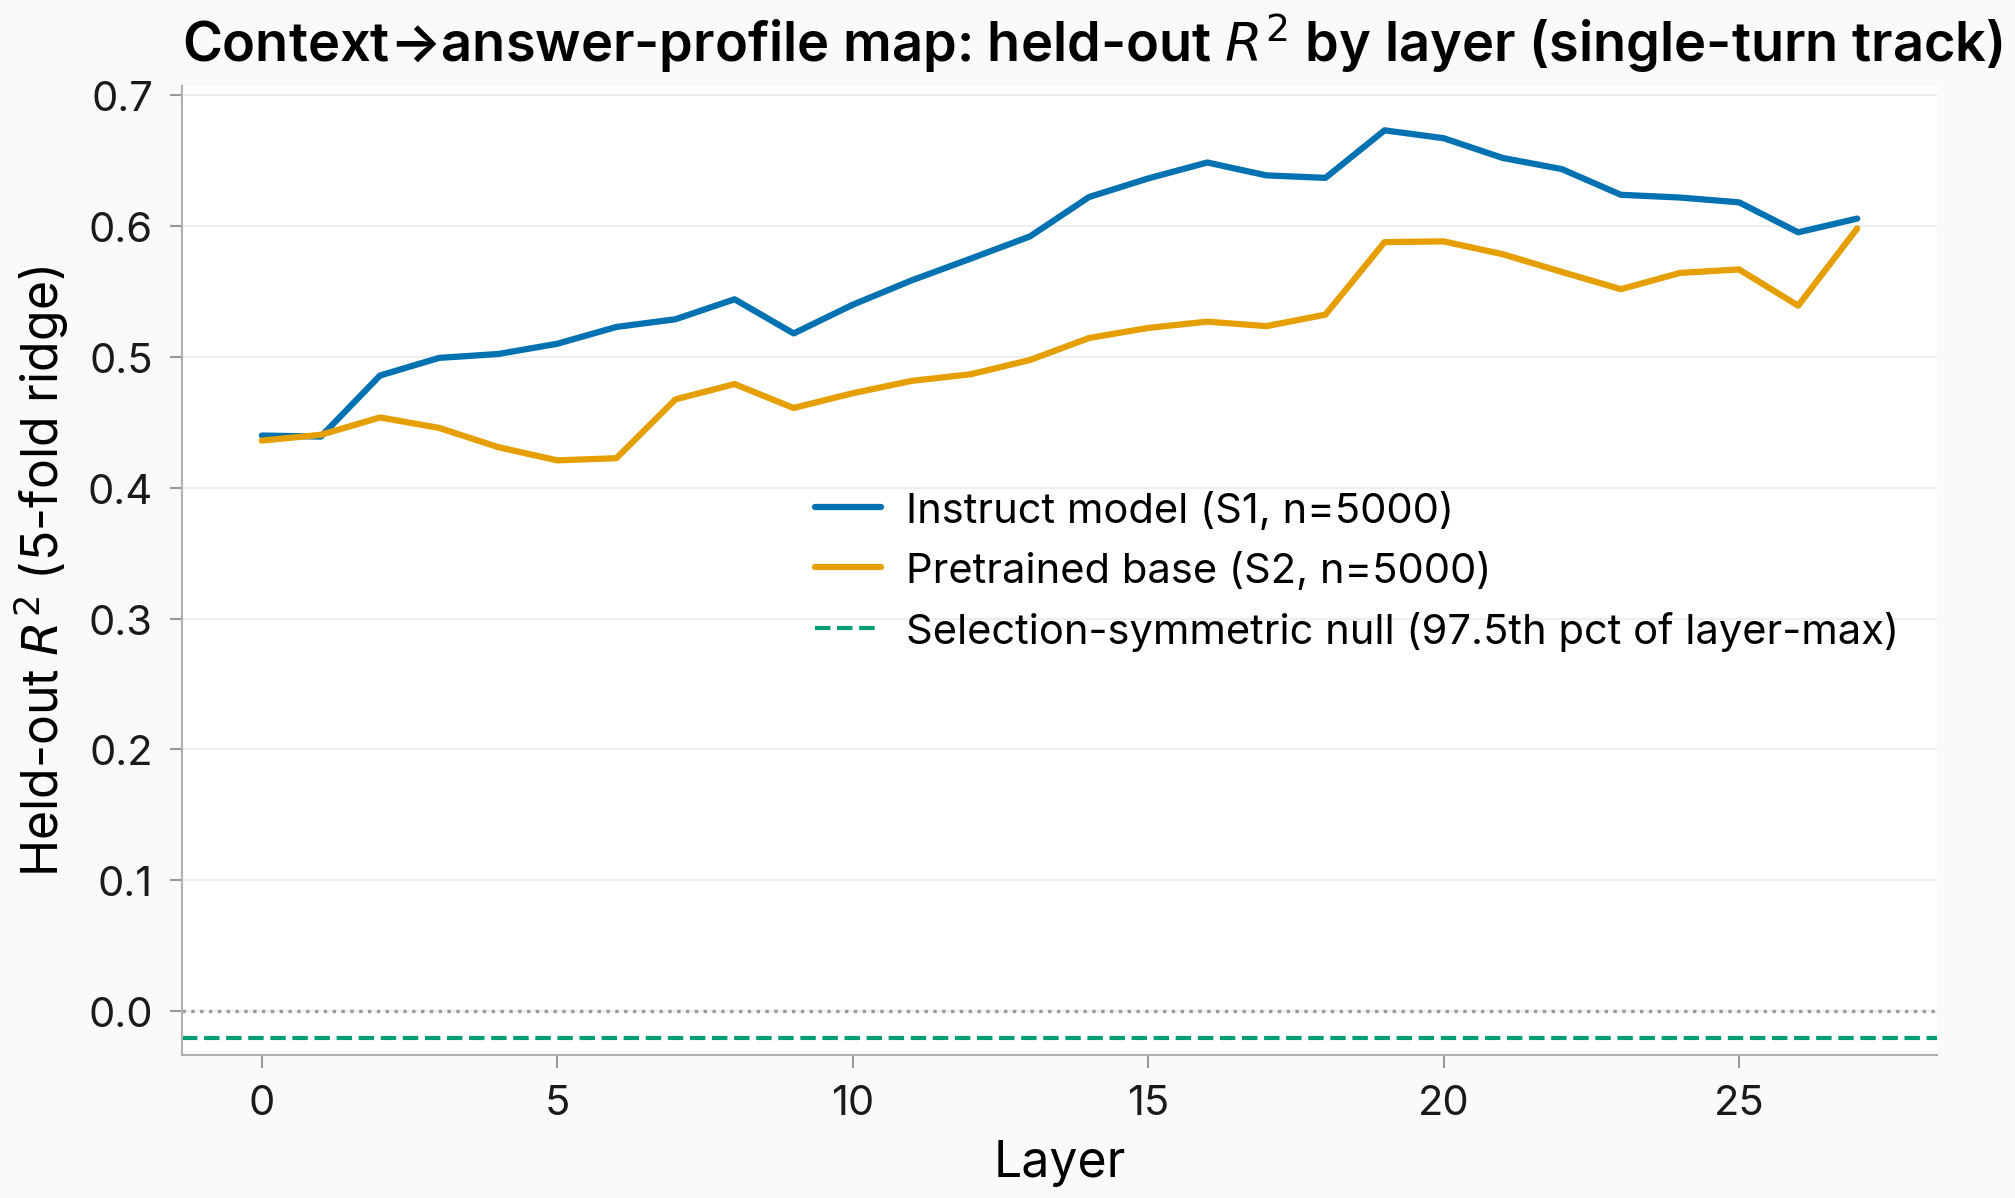
Takeaways:
- The mapping already mostly exists in the base model:
- Base 0.588 vs instruct 0.673 at the shared best layer 19 — 87.3% of instruct strength
Result 2: Post-training reparameterizes the existing map by a general linear map
I then wanted to see whether post-training builds a new map or just re-expresses the existing one
Methodology
- Fit the ridge operator M: context --> answer separately in base and instruct
- Fit a change-of-coordinates on the context side and answer side between the 2 models on identical text
- Test whether the base operator, reparameterized, is as good of a predictor of instruct text as the instruct operator
Takeaways:
- Reparameterizing the base model mapping with a general linear mapping gives as good of a predictor of instruct text as the instruct mapping
- This indicates the information to predict the instruct text is already present in the base model context vector
- this gives some indication that post-training is only eliciting capabilities and not teaching new ones (at least the ones that are linearly predictable from the context vector)
Update (matched-capacity null round, 2026-07-17): the equality is not a fitting-capacity artifact. Two matched-capacity fitted nulls at layer 19 (identical ridge core, folds, and n=5,000) collapse far below the observed 0.673 — refitting the cross-model change-of-coordinates on shuffled correspondence gives held-out −0.002, and replacing the base operator with a spectrum-matched random operator (same singular values, random subspaces) gives −0.25 (base→instruct) / −0.47 (instruct→base). A 1,000-draw conversation-grouped bootstrap places the reparameterized composition at the own-map ceiling: base→instruct comp−ceiling Δ −0.0003 (95% CI [−0.0024, +0.0019], indistinguishable), instruct→base +0.0012 (95% CI [+0.0003, +0.0021], a marginal +0.001 above). See scripts/issue825_reparam_matched_null.py, figures/issue_825/reparam_matched_null.png.
Result 2.5: What is the reparameterized base map?
I then wanted to see if there is a difference between the reparameterized base map and the instruct map (just because they have the same predictive power doesn't mean they are the same)
Takeaways
- Yes there is:
- if you rotate them to be as similar as possible then flatten and take cosine similarity, you only get 0.69
- so you need rescaling of directions to turn the base map's into the instruct's one
- Where is the change happening?
- how well instruct's context vectors can be linearly reconstructed from base's:
- how well instruct's answer vectors can be linearly reconstructed from base's:
- so most of the reparameterization is on the context side
Result 3: The mapping holds up without chat-template tokens (in both base and instruct model)
I then wanted to see if this mapping was only there because of the chat-template tokens.
Methodology:
- Re-render the same Track-S conversations (same response texts) with the chat template replaced by plain "User:" + "Assistant:" text, then refit the same ridge recipe in both models
- 4,724 of the 5,000 conversations survive the render/span-alignment filter; the paired contrast refits BOTH formats on this shared set (identical folds, seed 0) with a 1,000-draw conversation-level bootstrap on the naturalistic−chat delta
- Anchor gate: the chat refit first reproduces the committed Result-1 values (instruct 0.673 / base 0.588 at layer 19) to within 0.001
Takeaways:
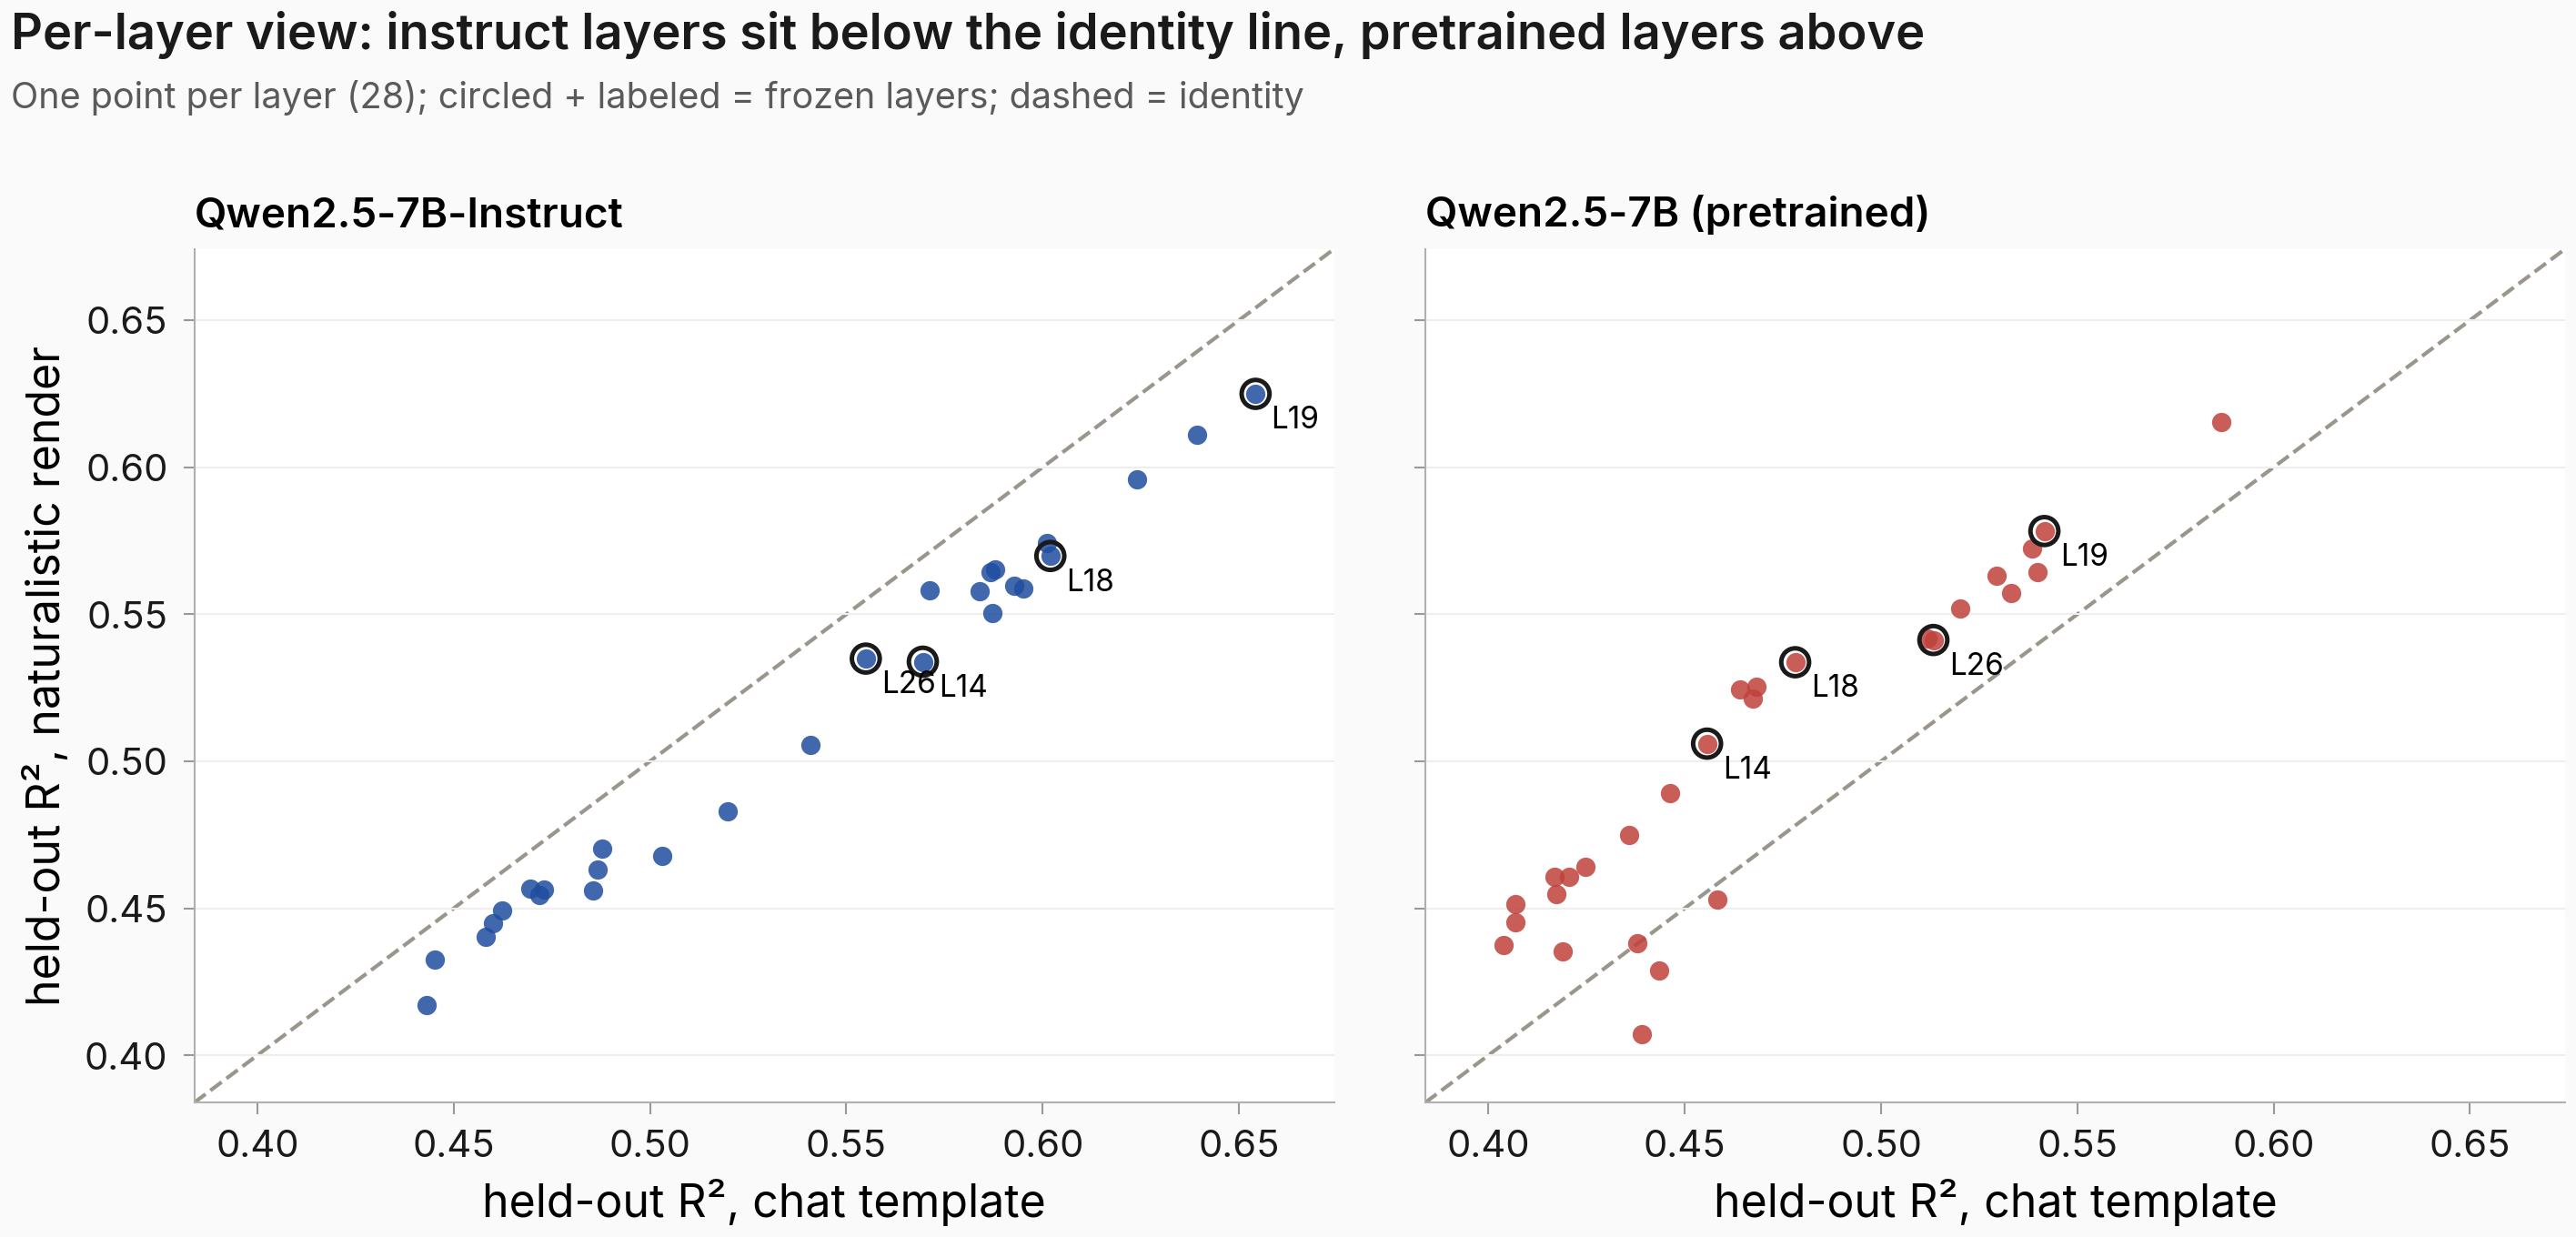
- The mapping holds up without chat-template tokens in both models: instruct (vs chat), base (vs chat) at layer 19 — all four cells sit ~0.6 above the shuffled-pairing null (≈ −0.03)
- Small format × model crossover, both deltas distinguishable from zero under the paired bootstrap: the template helps instruct slightly (−0.029 R² without it) and hurts the base slightly (+0.037 without it); the base advantage holds at all four frozen layers, the instruct cost is concentrated at layers 18–19
- Without the template the base reaches ~93% of instruct strength (vs ~83% chat at matched n) — the pretraining-inheritance picture gets stronger, not weaker, off-template
- Per-layer view: naturalistic vs chat R² scatter, one point per layer — instruct layers sit below the identity line, base layers above
- This indicates it is not a function of the chat template but more a function of general assistant -> output text
- Caveats: an earlier draft of this section quoted R² 0.71–0.74, which came from the #1092 naturalistic-transcript corpus — the numbers above are the final refit on this experiment's own conversations; the result JSONs were recovered from the crashed run's boot disk (the run finished fitting and died uploading); the planned MLP probe on the naturalistic cells was not run (ridge-only round)
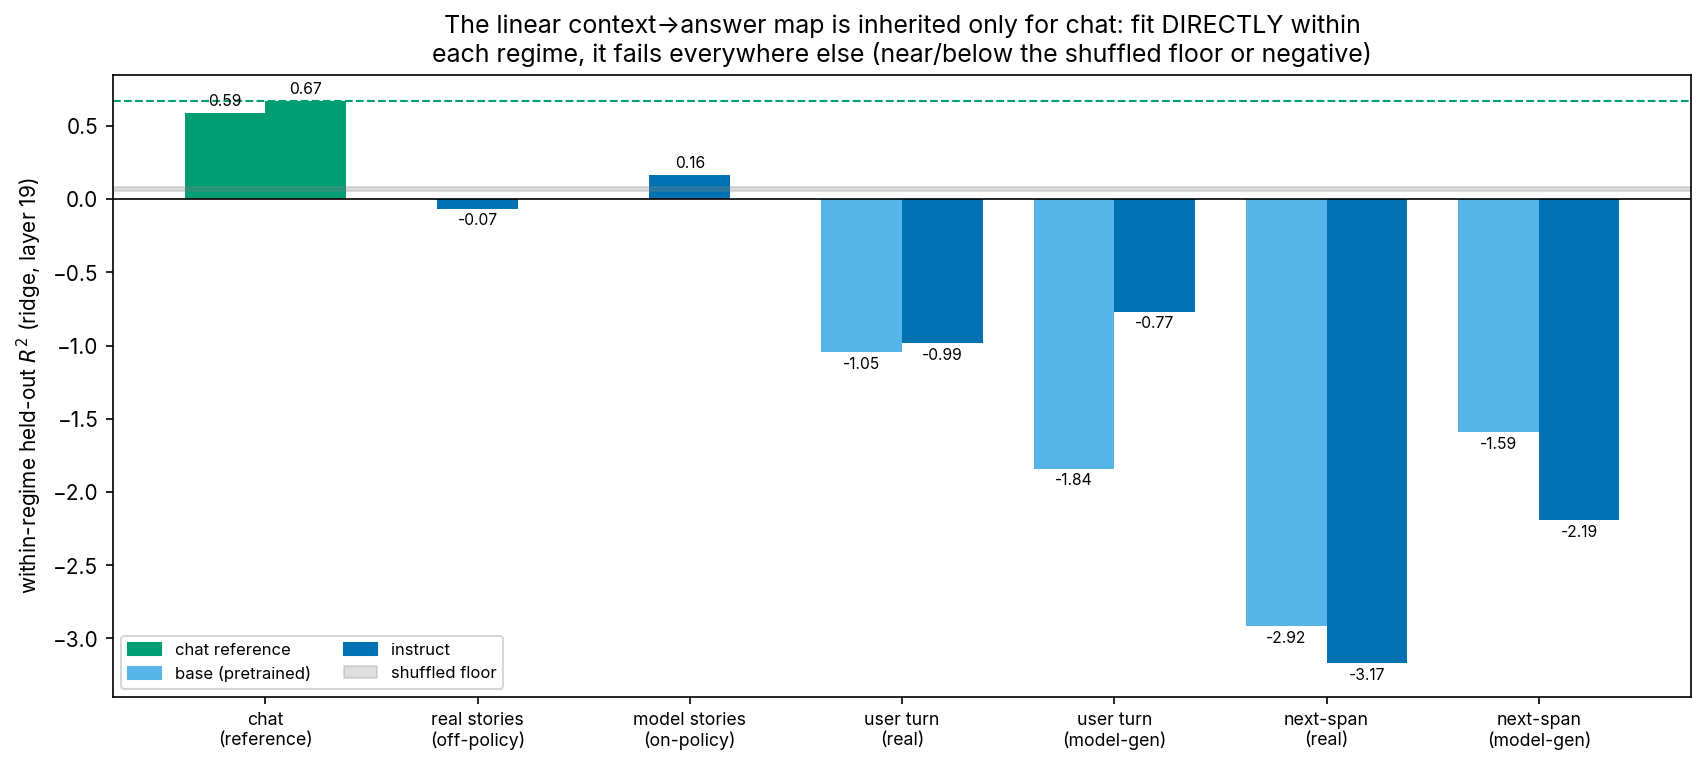
Result 4: The mapping does NOT hold up for generic stories, or for the user turn, or for generic next span prediction
I then wanted to see
- is this just a generic "character -> character output" mapping in stories(as might be predicted by PSM)
- does this mapping hold for the user turn?
- does this mapping hold for generic next span prediction (punctuation to span of text before next punctuation)
Methodology:
- Fit mapping to:
- character -> answer in generic real stories
- character -> on-policy generated answer in stories generated by the model
- user context -> user answer (from real data)
- user context -> user answer (generated by model)
- punctuation token -> next span of text before next punctuation (real generic data)
- punctuation token -> next span of text before next punctuation (generated by model)
- Plot for each
Takeaways:
- The mapping does not hold up for:
- generic stories (on and off policy)
- the user turn
- generic next-span prediction:
- I am thinking this is probably because it might be a "per-character" mapping (although the user turn not holding up somewhat disproves this)?
- potentially it is an "AI character mapping" because the model thinks it should be good at predicting text generating by an AI
Update (user-answer resample ceiling round, 2026-07-20): target-answer diversity does NOT explain the user-turn null. K=4 fresh claude-haiku-4-5 user-turn redraws per context (1,914 contexts, generation recipe reused verbatim from this experiment's conversation builder) put the within-context resample ceiling HIGH: inter-resample R² (leave-one-draw-out, K=4) 0.70 instruct-read / 0.68 pretrained-read, bias-corrected infinite-K ceiling 0.78 / 0.76 at layer 19 (0.76–0.81 across frozen layers) — only ~22–24% of user-answer activation variance is within-context sampling noise. Every fitted user-turn map sits far below this ceiling (byte-matched Haiku-u2 ridge −1.43/−1.49; Qwen-as-user ridge −0.77/−1.84, MLP 0.08–0.33), so the map failure is representational, not irreducible target diversity — with the caveat that "context-determined" includes any stable per-context structure, nuisance dimensions included. Sanity: the original Haiku turns are exchangeable with the redraws (LOO-e2 ratio 1.003/0.996) and the recapture matches the stored vectors (layer-19 cosine mean 0.99998). Figure; eval_results/issue_825/kresample-user/floor_summary.json + scripts/issue825_kresample_user_{gen,capture,floor}.py @ 91728e3615; raw draws + v(u2) tensors on the HF data repo under issue825_kresample_user/.
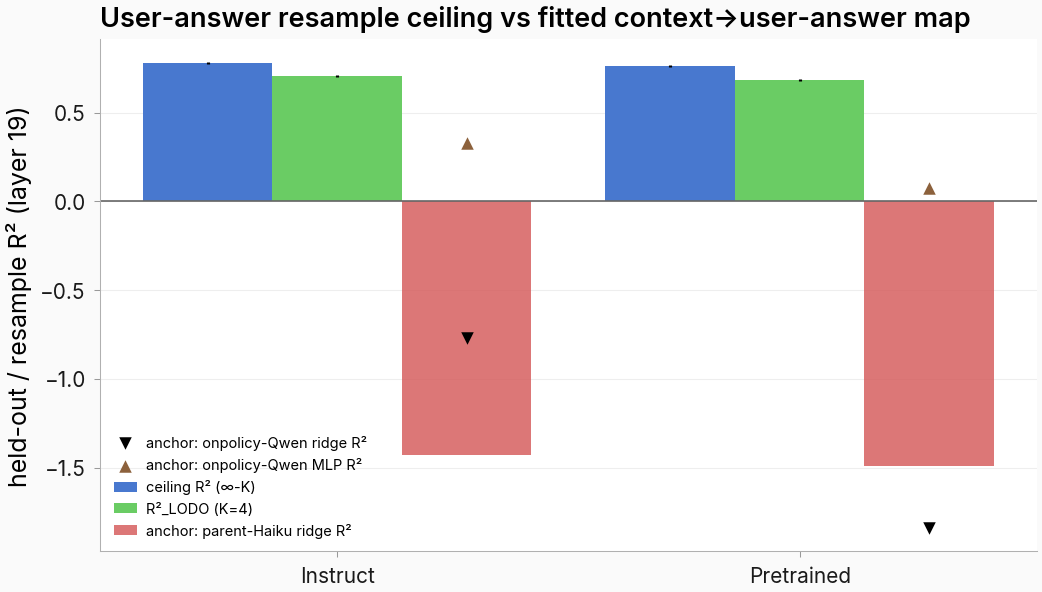
Update (selector-audit settle battery, 2026-07-25; folded into the body 2026-08-19 on Thomas's direction): the user-turn LINEAR null above is an estimator artifact of unguarded GCV λ-selection at n_tr < D — under a guarded selector (GCV_DOF_CAP=0.9) all four user cells flip from ridge R² −1.43…−1.65 to +0.19…+0.25, matching the banked MLP band (0.19–0.23). Corrected read: the user's next turn is weakly linearly predictable (~0.2), ~2.5× below the assistant on the same rig — the role asymmetry survives, the linear-vs-nonlinear gap does not. This also bounds the 2026-07-20 note's "representational failure" framing: the fitted maps sit at ~0.2 against a ~0.78 resample ceiling — a large but finite gap, not a null. Artifacts: eval_results/issue_825/trackm_settle_battery/ @ cf32ce168b.
Result 4.5: Story characters DO carry the map once properly powered — the initial weak read was an n≪p artifact (instruct control pending)
I wanted to test this hypothesis and see if a mapping trained on single character outputs in stories existed.
Methodology
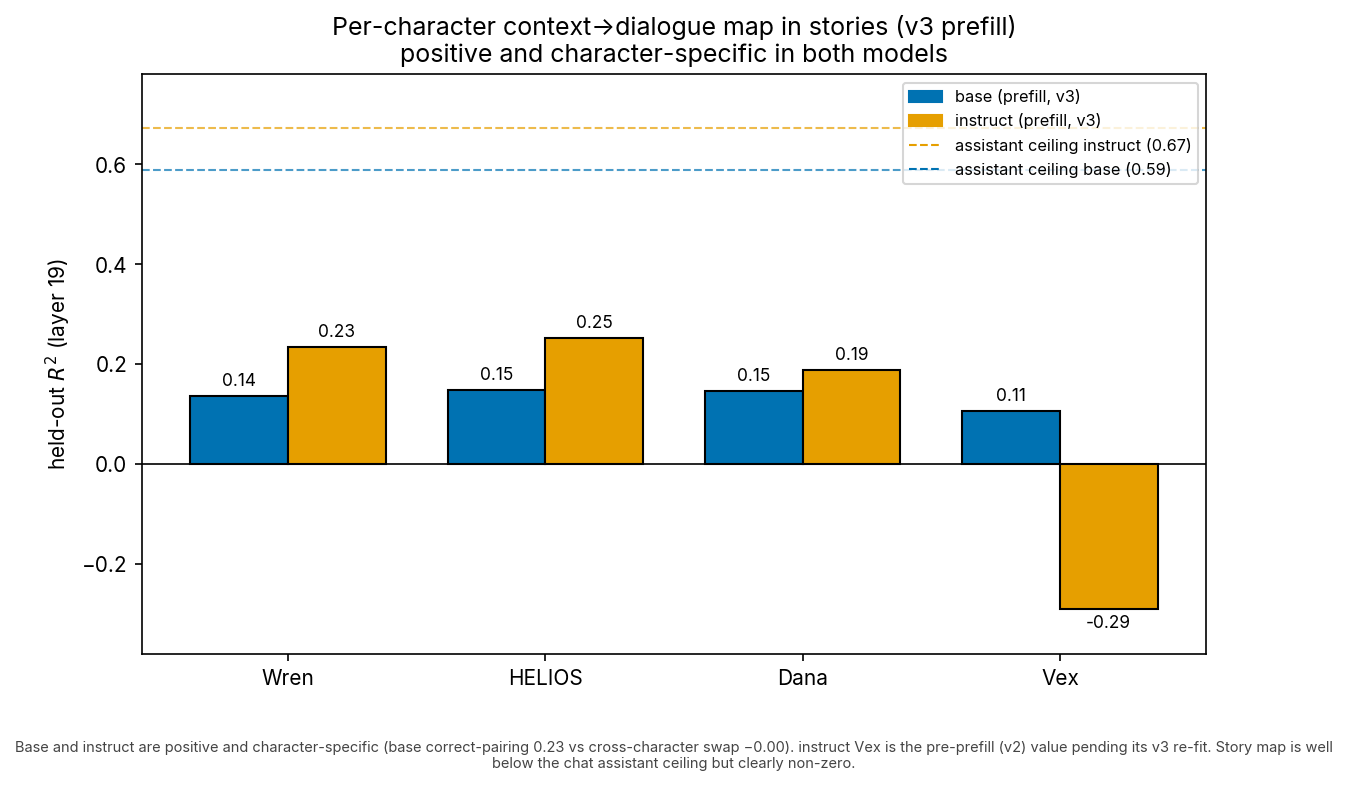
- Tell model to generate stories with 4 different characters:
- Wren: warm assistant
- HELIOS: calm AI
- Dana: ordinary person
- Vex: theatrical villain
- Examples
- Both base and instruct model
- Plot for each character
Takeaways
- The weak/inconsistent read in the figure above was an underpowered v2 artifact (n ≪ p; e.g. the instruct Vex / swap cells sat at n = 149 / 524); the #1310 properly-powered re-run (run-2, model-generated labeled script-format scenes, ~1.3–3.6K pairs per character) flips it
- Base model held-out (script-format cells, committed at
60aaea309a): Wren 0.137 / HELIOS 0.148 / Dana 0.147 / Vex 0.106; correct-character pairing 0.233 vs cross-character swap −0.002 → the map is per-character, not generic (which also explains Result 4's pooled generic-story null: a cross-character map is ≈ 0) - Instruct (partial — run-2 crashed before fitting instruct Vex + the instruct swap control): Wren 0.235 / HELIOS 0.253 / Dana 0.188 — positive and stronger than base
- This largely dissolves the "why does User:/Assistant: hold up when story-like doesn't" question: story characters DO carry the map — the assistant's is just ~3–5× stronger (~0.65 chat) — so the open question is the magnitude gap, not presence/absence
- HELIOS (the AI character) ≈ Wren/Dana cuts against the "AI character mapping" hypothesis from Result 4 — being an AI character alone doesn't buy assistant-level strength
- Caveats: the figure still shows the superseded v2 read; the 2026-07-15 "v3 RESULT" marker mislabeled these run-2 script-format cells as v3-prefill (forensics: every cell records git_commit=942df1bb2a, and v3 @0a0e9cfd ran only ~22 min before crashing); a clean full on-policy-prefill refit (all 4 characters × both models + swap controls in both — prefill data already generated and local) is in flight 2026-07-16 and will supersede these numbers; until it lands the instruct specificity control remains open
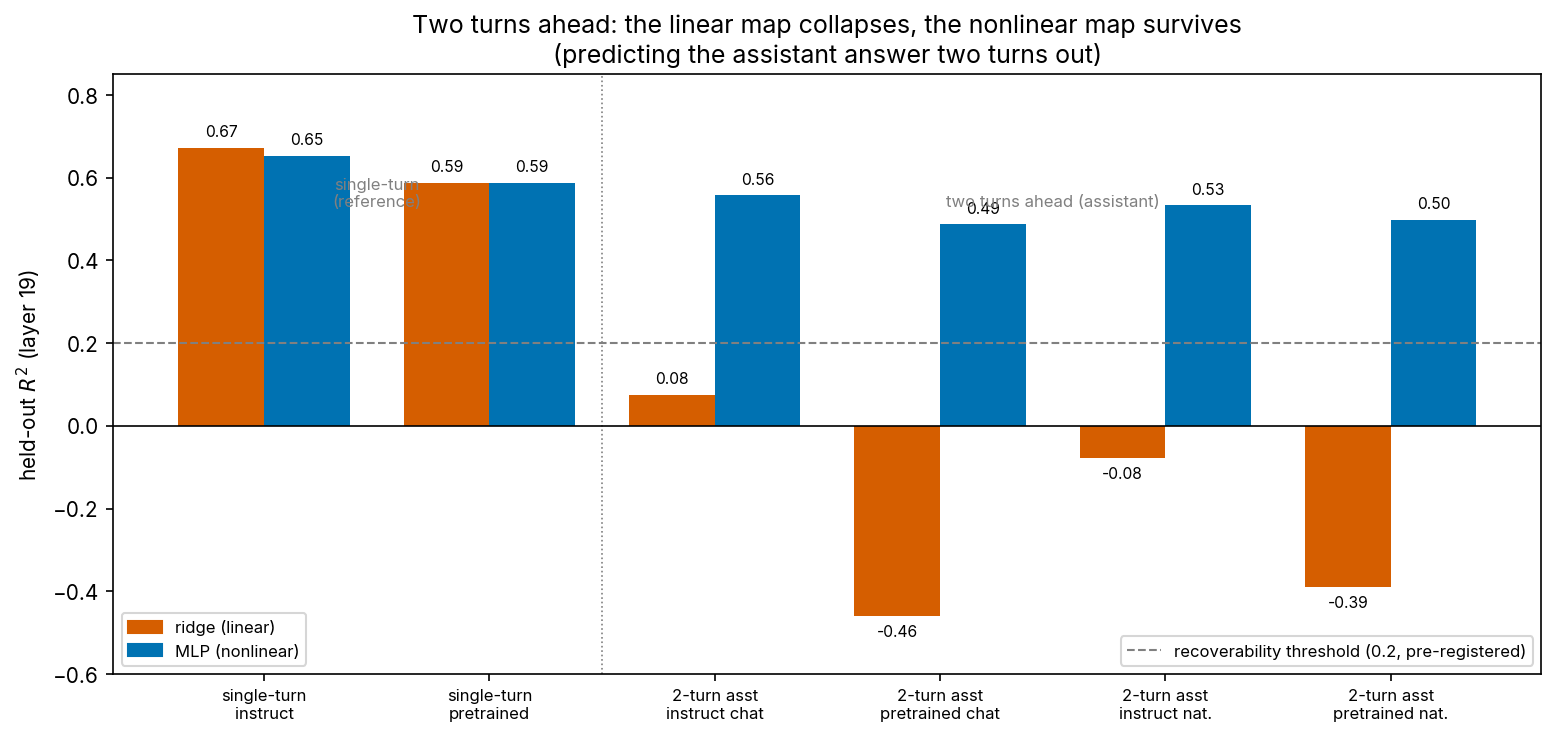
Result 5: The linear mapping breaks across two-turns, but the nonlinear mapping holds
I then wanted to see if you can predict the assistant answer in 2 turns from the current turn's context (both linearly and nonlinearly)
Methodology:
- Train linear and nonlinear mapping from context vector to answer vector for assistant in 2 turns
- Plot
Takeaways:
- There is no linear mapping from context vector to answer vector for the assistant in 2 turns
- There is a nonlinear mapping from context vector to answer vector for assistant in 2 turns ()
- This suggests the information is there but it is not linearly decodable - kind of a strange result... where does the nonlinearity come in?
Update (turn-dynamics round, 2026-07-16): superseded by Result 9 — at n=5,000 with the parity-gated ridge the two-turn-ahead LINEAR map is positive ( 0.29 instruct / 0.13 base, vs +0.08 to −0.46 across the four two-turn cells here at n=2,000), and the round's matched MLP probe shows no nonlinear advantage. The two MLP probes differ in recipe (full-dimension input + PCA-64 target head at n=2,000 here vs PCA-256 input + PCA-48 target at n=1,000 there), so the nonlinear side is bounded rather than refuted; reconciling the probes is a named follow-up. Settled by the 2026-07-25 selector-audit settle battery: guarded refits put the M assistant cells at ridge 0.49–0.59 (at/above matched clean single-turn S at the same n), and the matched MLP probe ≈ guarded ridge (0.557 vs 0.588 instruct; 0.487 vs 0.493 base) — the two-turn "collapse" was the unguarded λ selector, not missing linear information.
Result 6: The per-turn mapping persists at every turn depth at roughly half single-turn strength — on-policy answers recover only part of the gap
The single-turn mapping ( at matched n) predicts the model's OWN answers, but on real logged multi-turn conversations the per-turn map came out much weaker. I wanted to isolate whether that residual comes from answer provenance (the logged answers were written by other models/humans) or from the multi-turn real-user corpus itself.
Methodology:
- 497 real logged multi-turn conversations (WildChat/LMSYS, ≥2 turns; 2,572 turn–answer pairs; per-turn cells kept at n ≥ 30, assistant turns 1–23)
- Contexts identical between arms: the real logged conversation up to each turn-k user query
- Two answer arms per turn: the real logged assistant answer vs the model's own on-policy answer to the same query (one draw, temperature 1.0, matching the single-turn generation recipe)
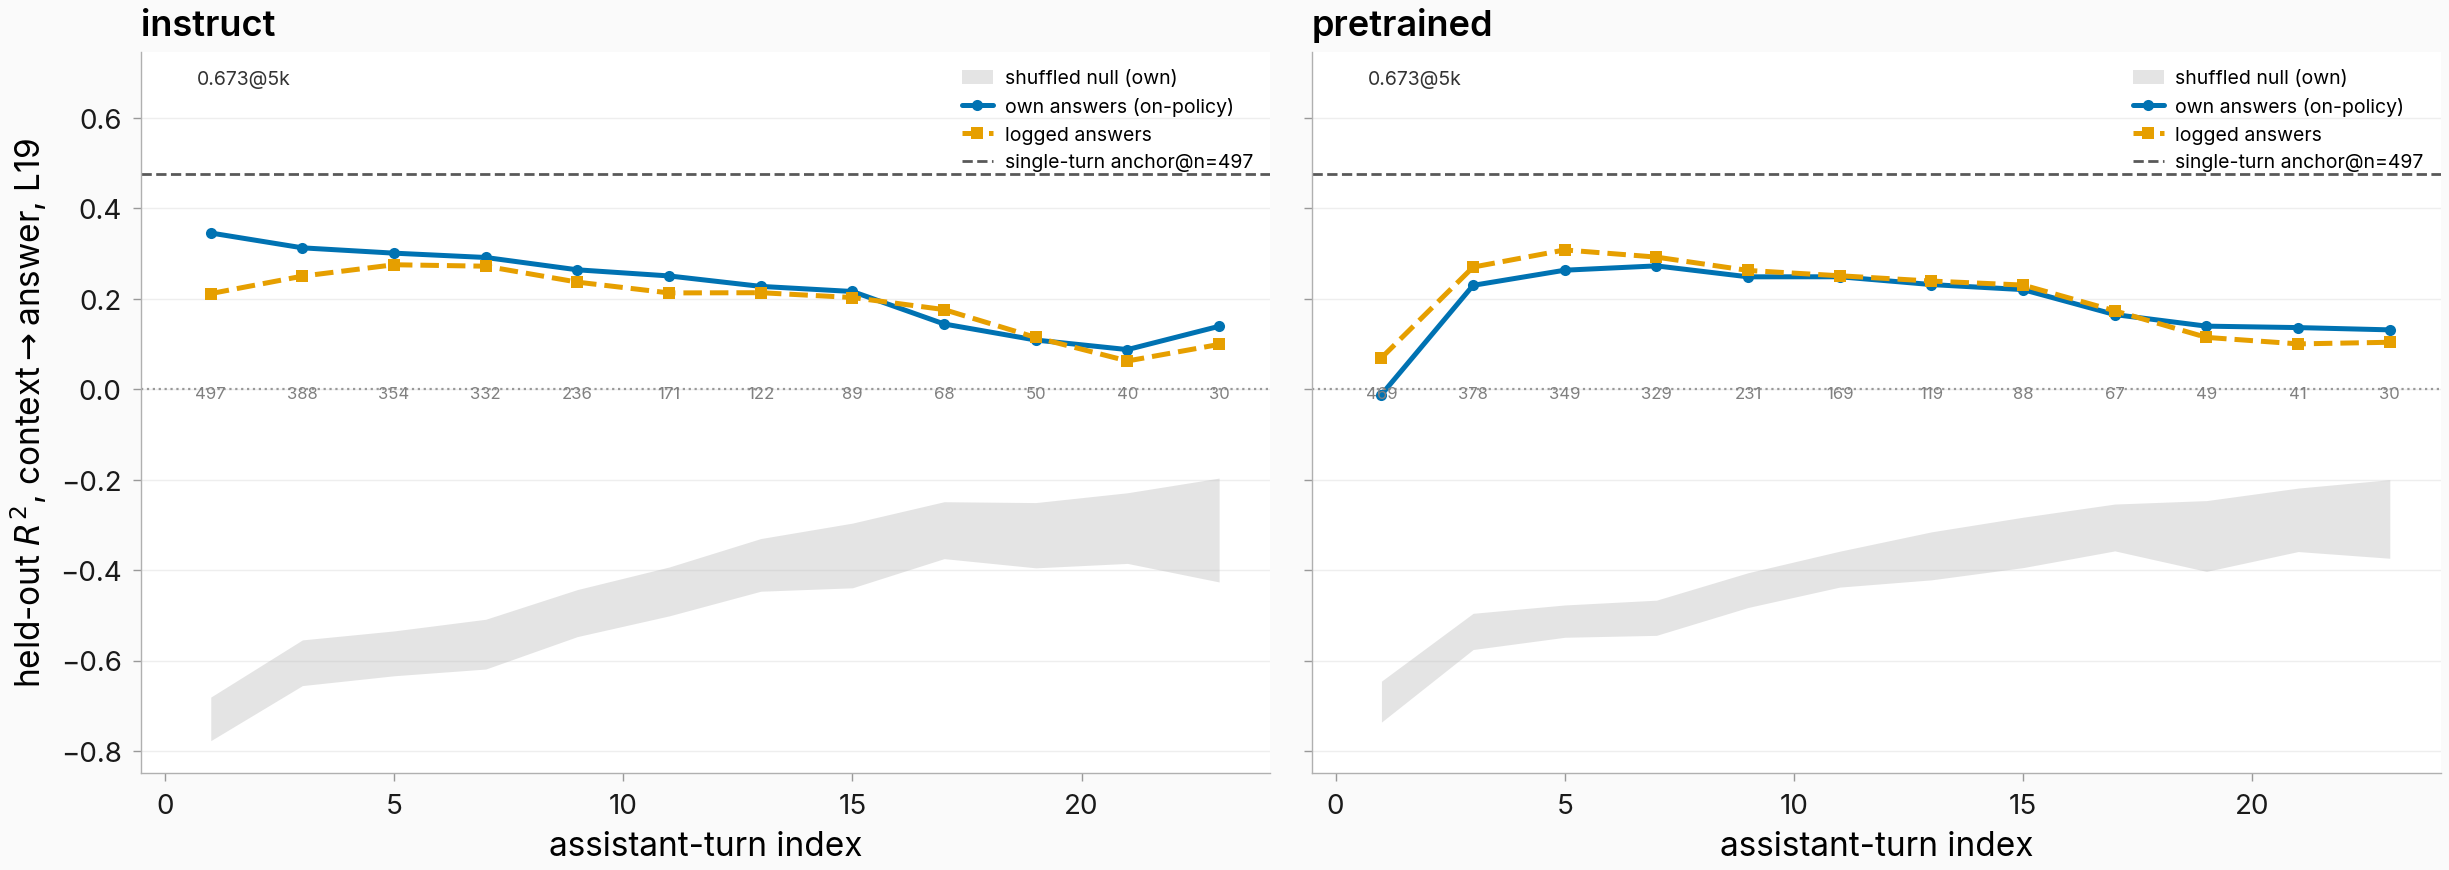
- Same ridge recipe (held-out , grouped 6-fold CV), layer-19 headline; shuffled-answer null per turn; paired conversation-level bootstrap on the own−logged delta; both mapping arms fit — context (everything before the answer, including the query) and prefix (everything before the user query)
- Single-turn anchor re-verified this round: at matched n=497
Takeaways:
- The mapping exists at every turn depth — all cells clear the shuffled null by a wide margin — but at roughly half the single-turn strength, decaying slowly with depth (instruct own: 0.35 at turn 1 → ~0.11 by turn 19)
- On-policy answers help most at turn 1 (instruct: 0.212 → 0.346) and only +0.04 pooled across all turns, both distinguishable from zero under the paired bootstrap; the two curves converge by turn ~13
- Even with own answers, turn 1 reads 0.35 vs the 0.476 single-turn anchor at the same n — provenance contributes, but most of the multi-turn gap is the corpus (real-user multi-turn conversations vs the curated single-turn set), not who wrote the answer
- In the pretrained model own answers are slightly less predictable (pooled −0.02; turn 1 −0.08): the base model's temperature-1.0 completions on the raw-text multi-turn render are noisier than the logged ones
- The prefix arm stays near zero at every depth (−0.10 to +0.08, both models, both provenance arms; structurally degenerate at turn 1) — the map runs through the query-inclusive context, not the pre-query state alone (prefix-arm figure)
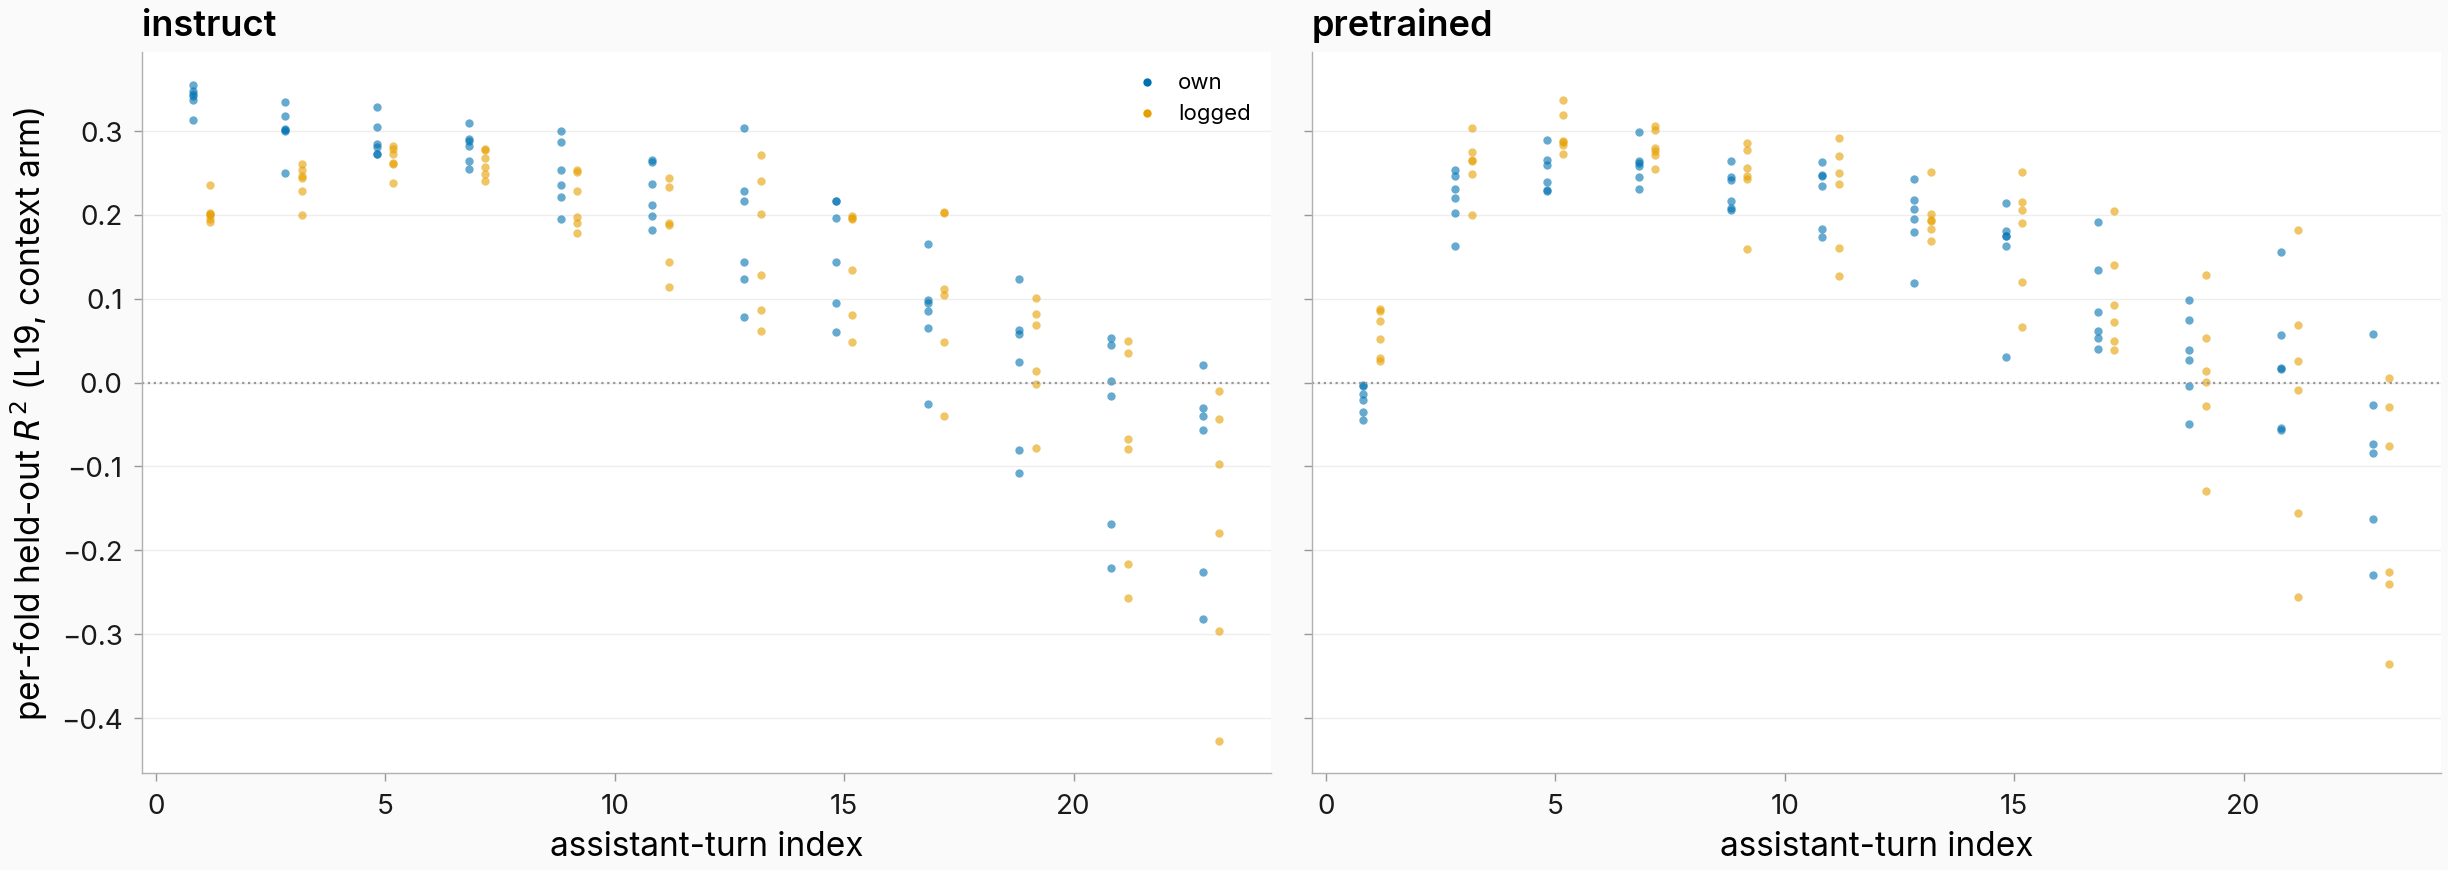
- Not an answer-length artifact: own answers are ~2× longer (median 394 vs 185 tokens), but the instruct gain survives within logged-length tertiles (+0.04 / +0.07 / +0.07) — per-fold points and layer-14/18 + length panels: folds, exploratory panels
- Caveats: one generation draw per turn, so deep-turn cells (n ≲ 60) are exploratory; 60 of 2,572 pretrained pairs (28 at turn 1) were dropped pair-safe from both provenance arms where a tokenizer merge at the plain-text answer boundary shifts the span position; the single-turn anchor recipe differs slightly (5-fold vs 6-fold here); instruct dropped 1 pair for context-window overflow
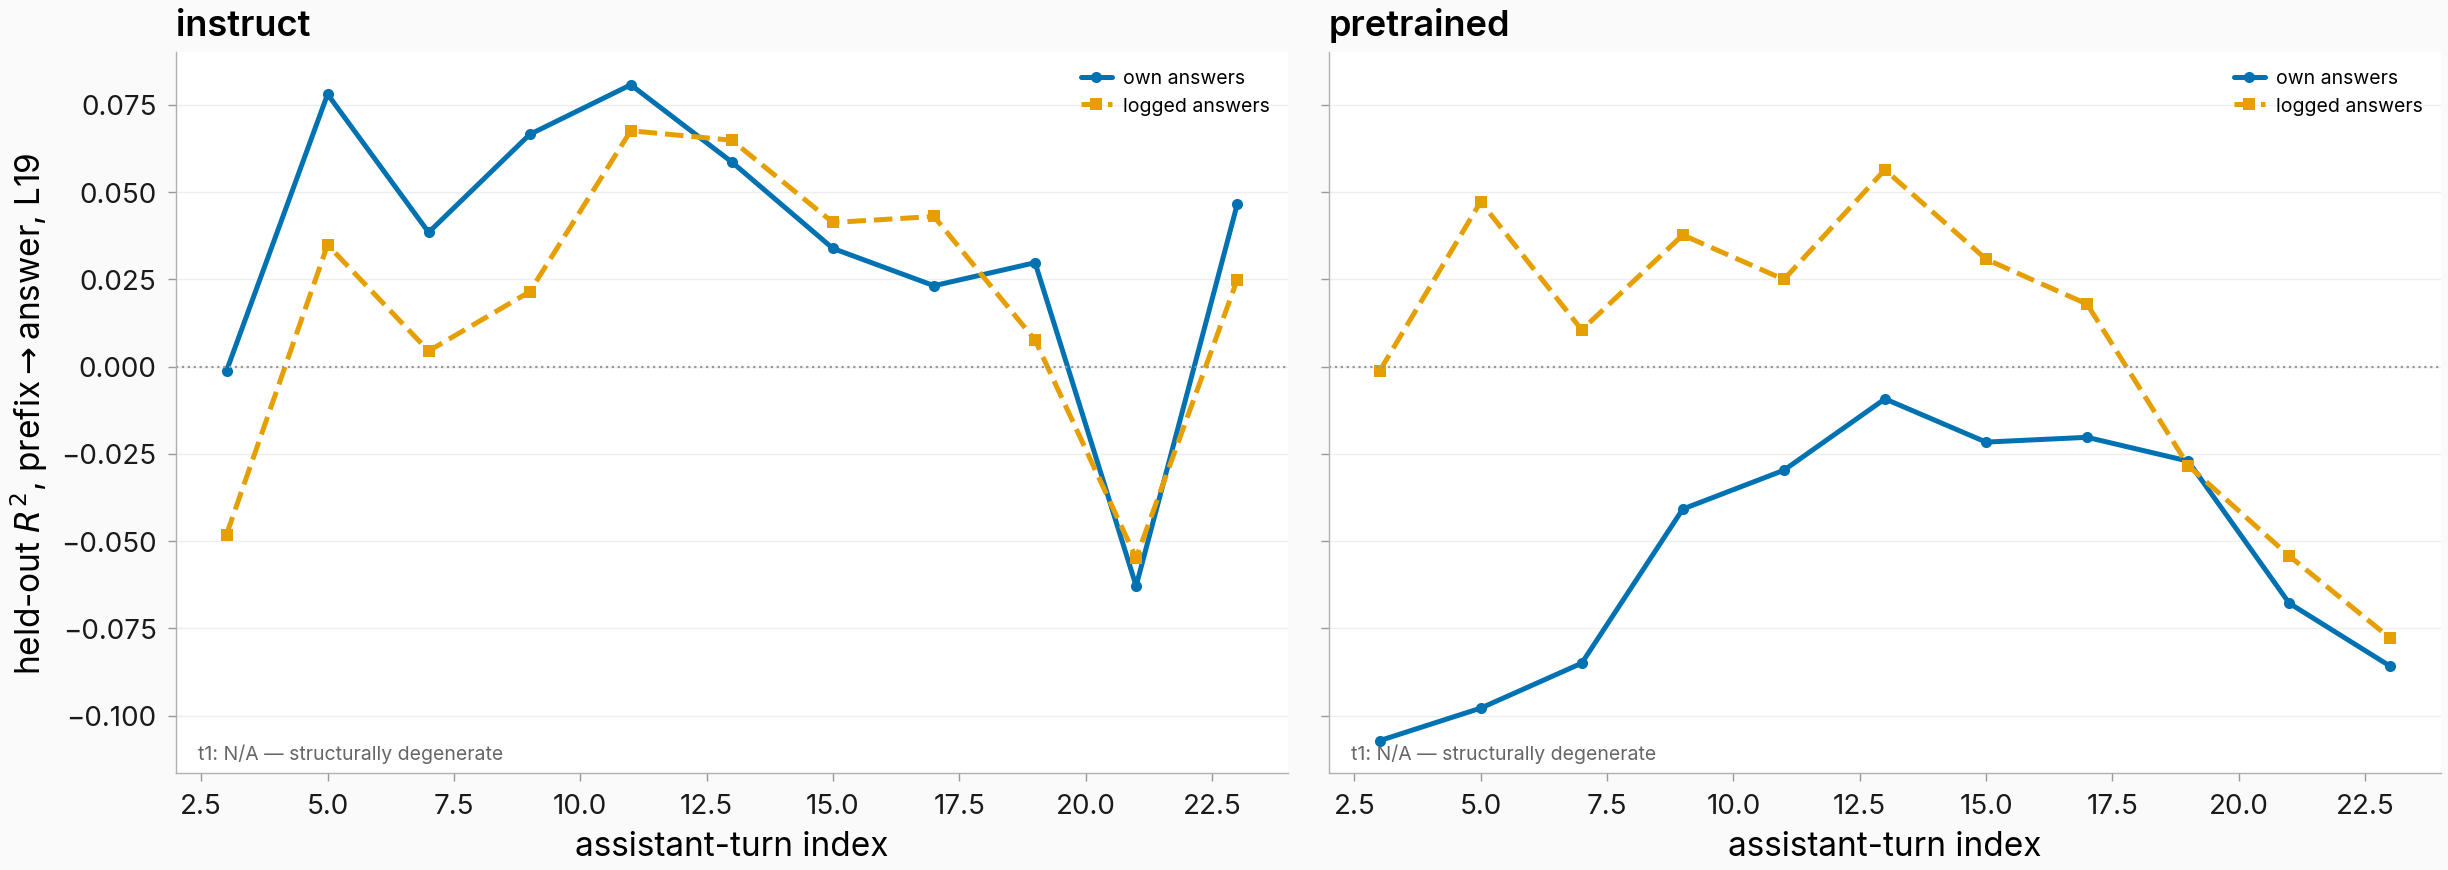
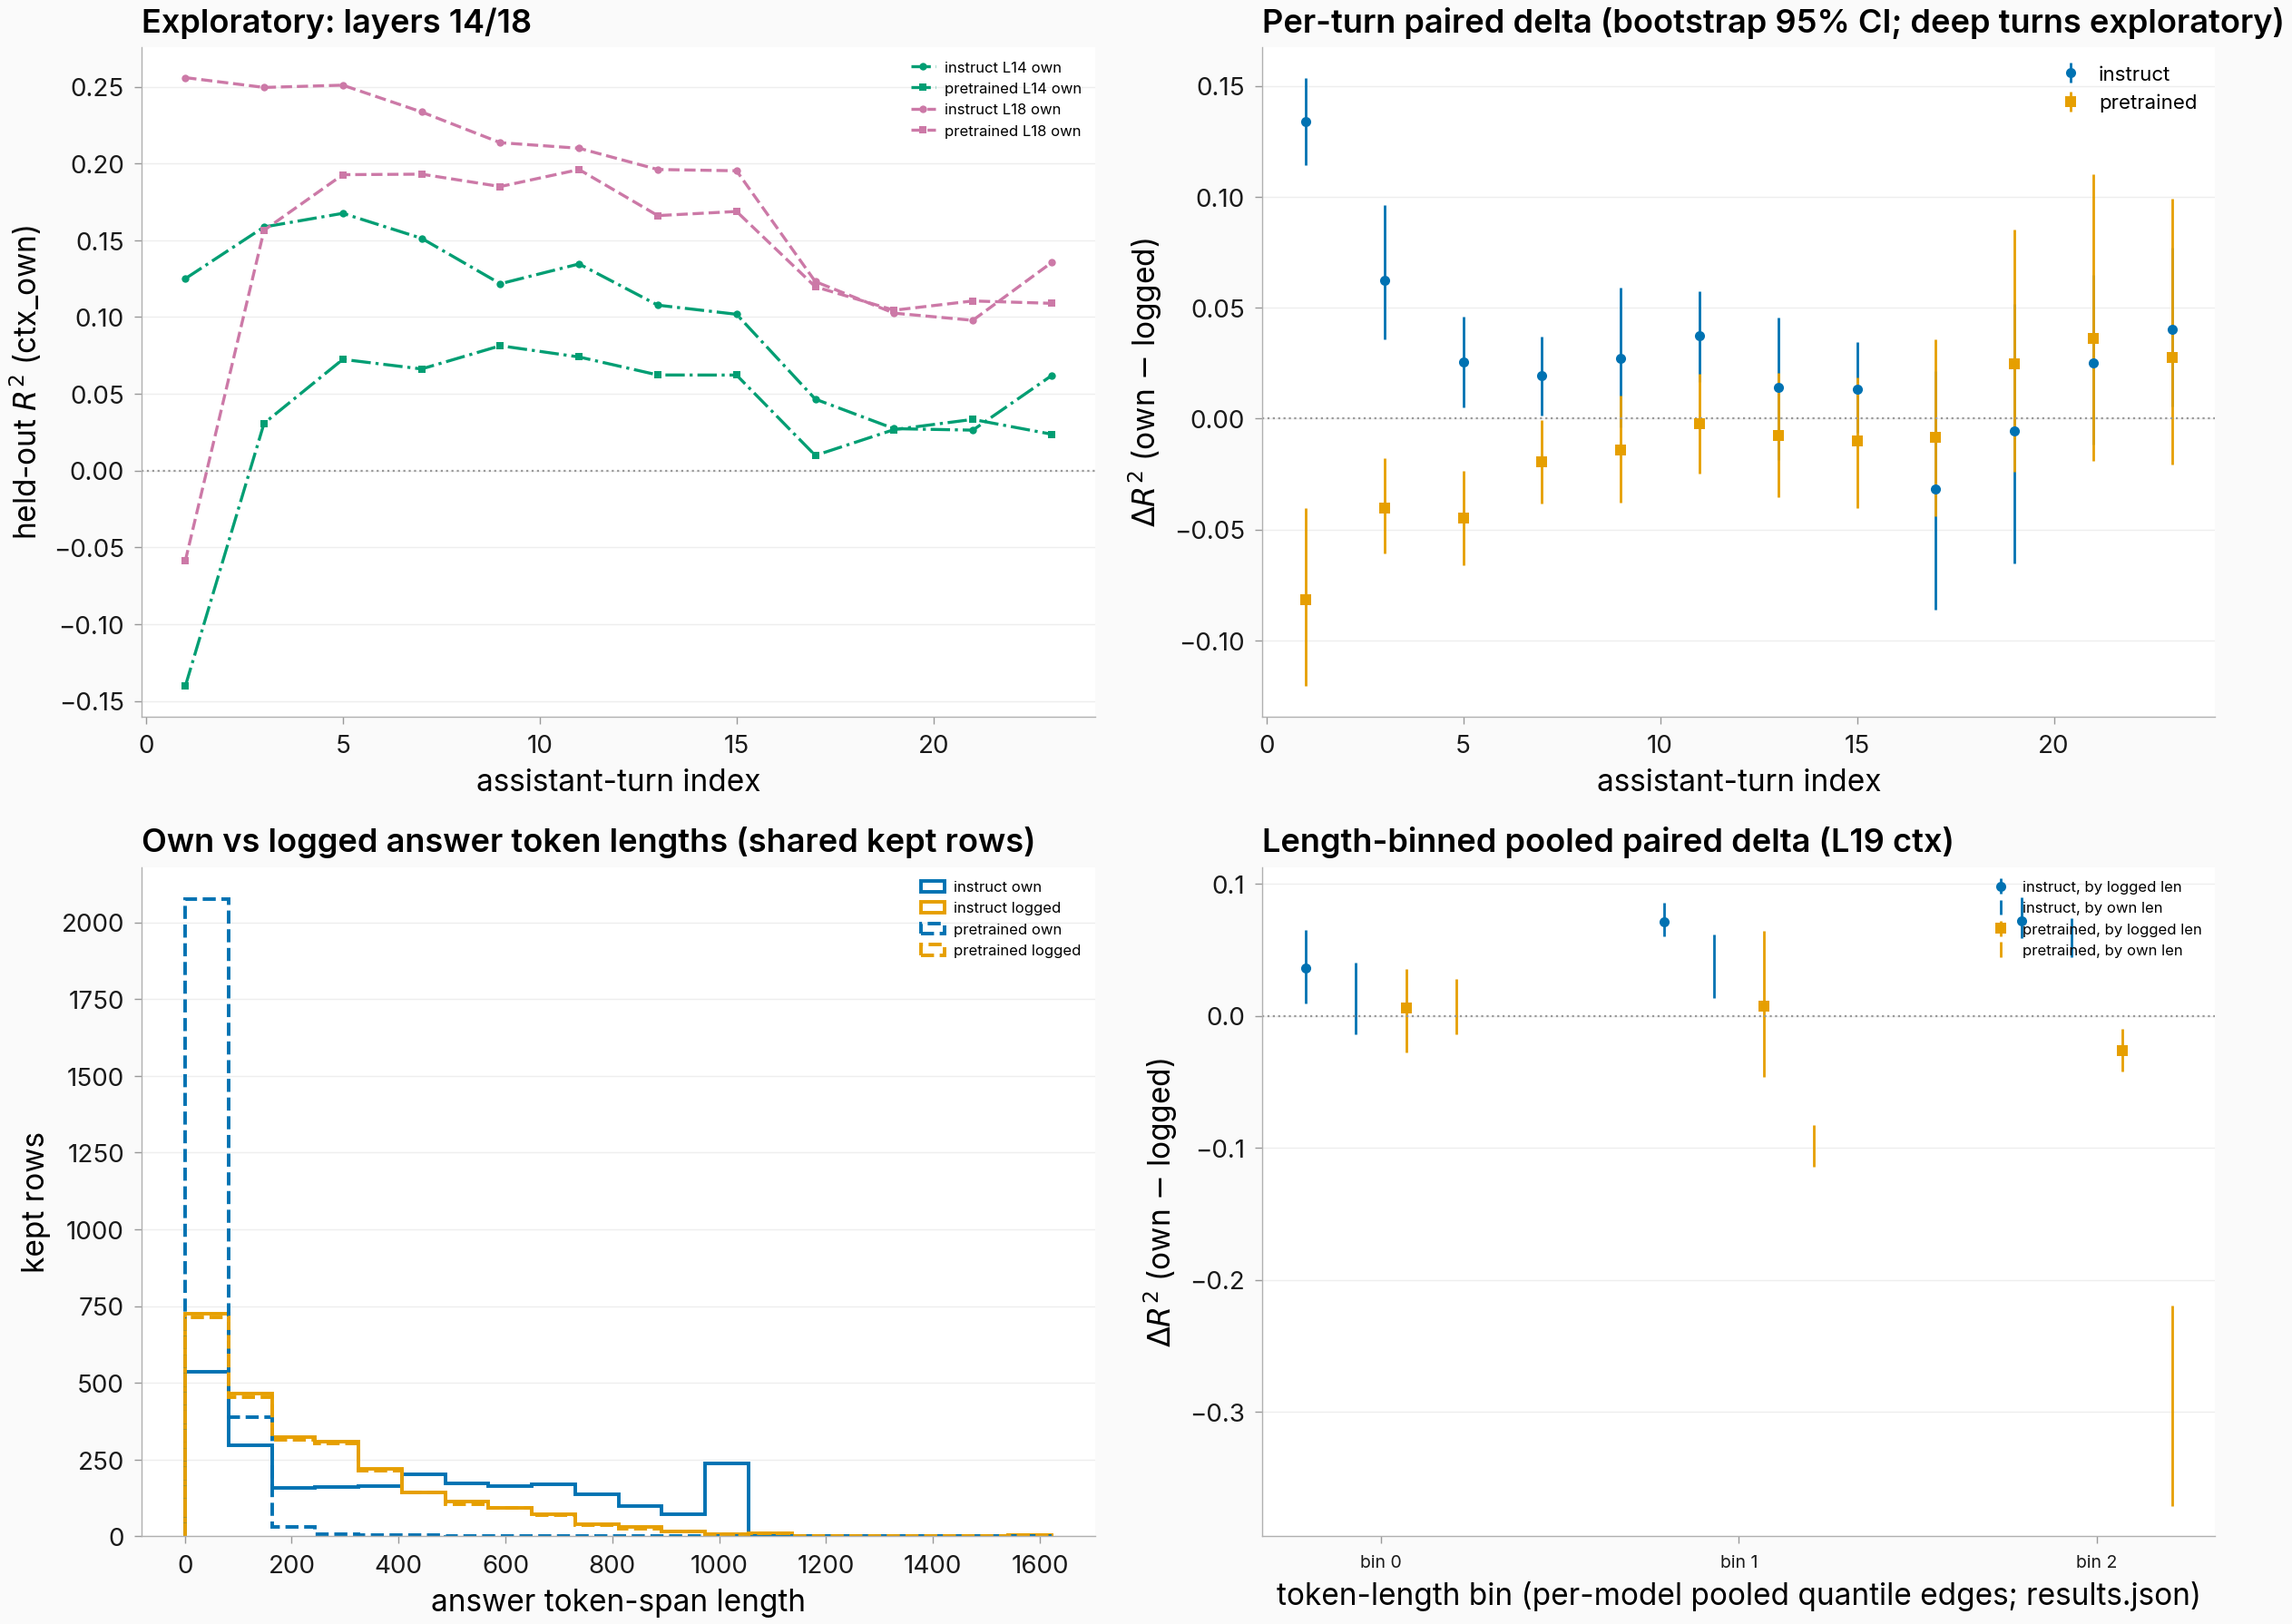
Update (turn-dynamics round, 2026-07-16): the depth story (a map at every depth, above null) holds; the magnitude and prefix reads are superseded by Result 7 — at n≈5,000 per turn the map is flat at ~81–88% of the single-turn anchor (not half, not decaying: this round's decay tracked its per-turn n shrinking 497→30), and the prefix arm is clearly positive once powered ( 0.26–0.47 from turn 2 on, not near-zero). The parity refit reproduces this round's 497-conversation numbers exactly, so these cells were computed correctly but underpowered. The provenance deltas replicate at 10× n (instruct own − logged +0.030 mean over turns 2–12, +0.094 at turn 1; base −0.007).
Result 7: At n≈5,000 per turn the mapping runs at near single-turn strength at EVERY depth — and the base model catches up with depth
Result 6 was capped at n=497 real conversations. I re-ran the per-turn map at flat n≈5,000 per turn, on real data as deep as real data goes and simulated continuations beyond.
Methodology (this result):
- Arm "real": 5,000 real logged conversations with ≥12 assistant turns (WildChat+LMSYS); forced logged context, the model writes turn k's answer (temperature 1.0, one draw) — Result 6's construction at 10× n, turns 1–12; a capture-only logged-answer arm rides along (turns 1–13 flat, plus the real tail to turn 30 at decaying n)
- Arm "simulated": the same 5,000 real openers extended to 16 assistant turns — claude-haiku-4-5 writes the user turns (one persona brief per conversation), the subject model's own answers accumulate on-policy (temperature 1.0, one draw per turn); n=5,000 at every turn 1–16
- Same ridge recipe (held-out , conversation-grouped 6-fold CV, layer 19), 200-draw shuffled-answer null per turn; the round-10 parity gate passed (see Methodology)
Takeaways:
- The per-turn map is FLAT at full power: instruct 0.55–0.59 at every turn in both arms, ~81–88% of the 0.673 single-turn anchor; instruct flat-n cells clear their shuffled null (≈ −0.12 to −0.19) by ≥0.66, every cell by ≥0.5
- The base model starts at 58% of instruct at turn 1 (0.344 vs 0.590), matches it by turn ~4, and reaches 0.651 by turn 16 in the simulated arm — post-training's advantage on this map is concentrated at turn 1
- The prefix arm is clearly positive once powered: instruct 0.29 at turn 2 rising to ~0.44–0.47 by turn 5 (simulated; 0.26–0.30 on real contexts) — the pre-query state alone carries ≈half of the context read from turn 2 on (52% simulated instruct at turn 2; 47–50% real instruct at turns 2–3, 40–44% pretrained at all depths), rising to ~80% at depth in the simulated arms
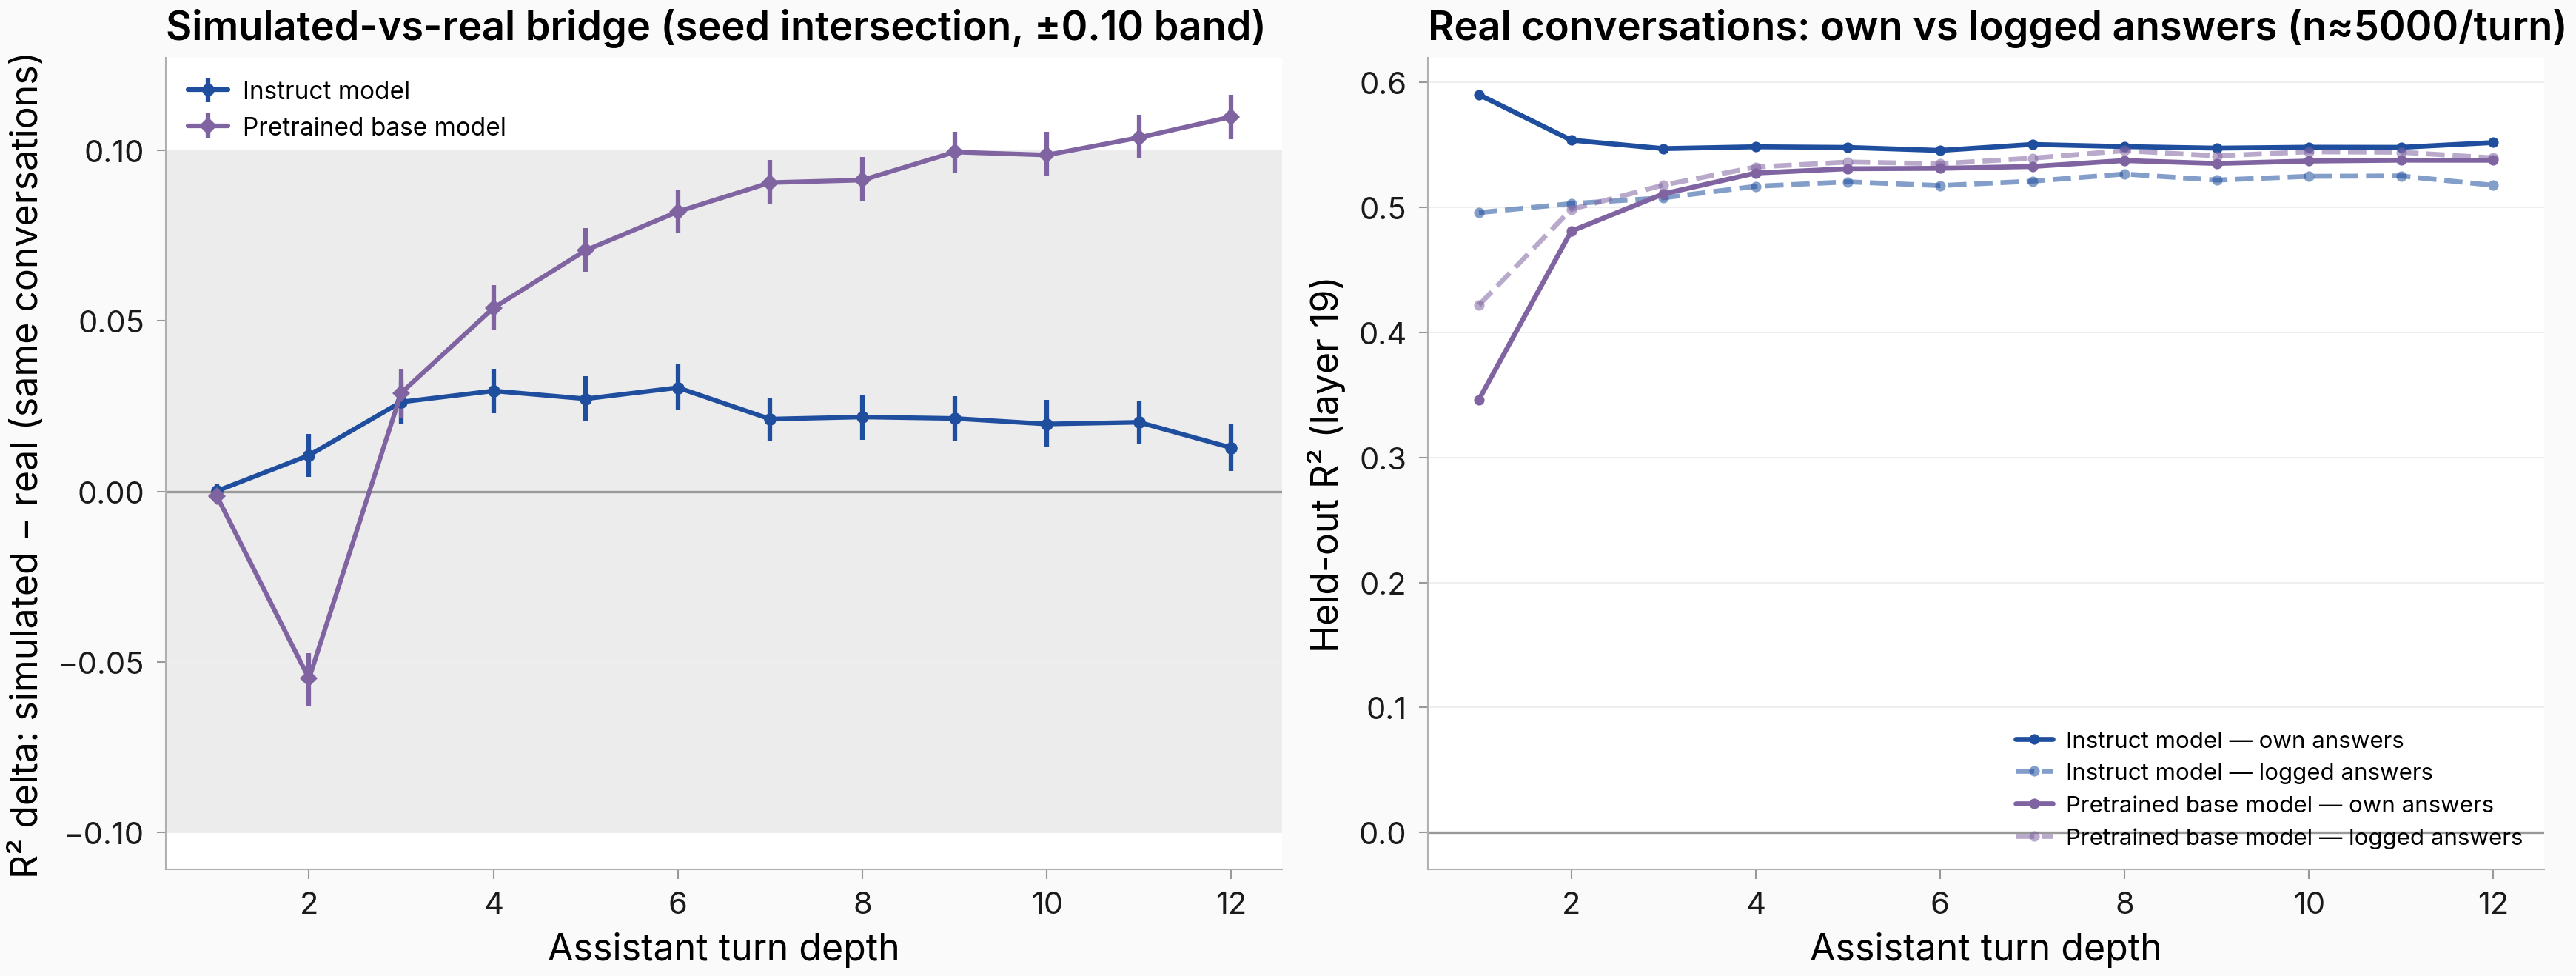
- Logged answers track own answers ~0.03 lower (instruct; +0.09 gap at turn 1) and ~0.01 higher in the base model — Result 6's provenance read at 10× n
- Simulated-vs-real bridge (same conversations, turns 1–12): instruct within ±0.03 everywhere; the base model dips to −0.055 at turn 2, then rises monotonically to +0.104/+0.110 at turns 11–12, just past the ±0.10 band — deep-turn base-model claims from the simulated arm carry a synthetic-gap caveat (the simulated user turns also grow more self-similar with depth: cross-turn cosine p90 0.31 at depth 2 → 0.56 at depth 16)
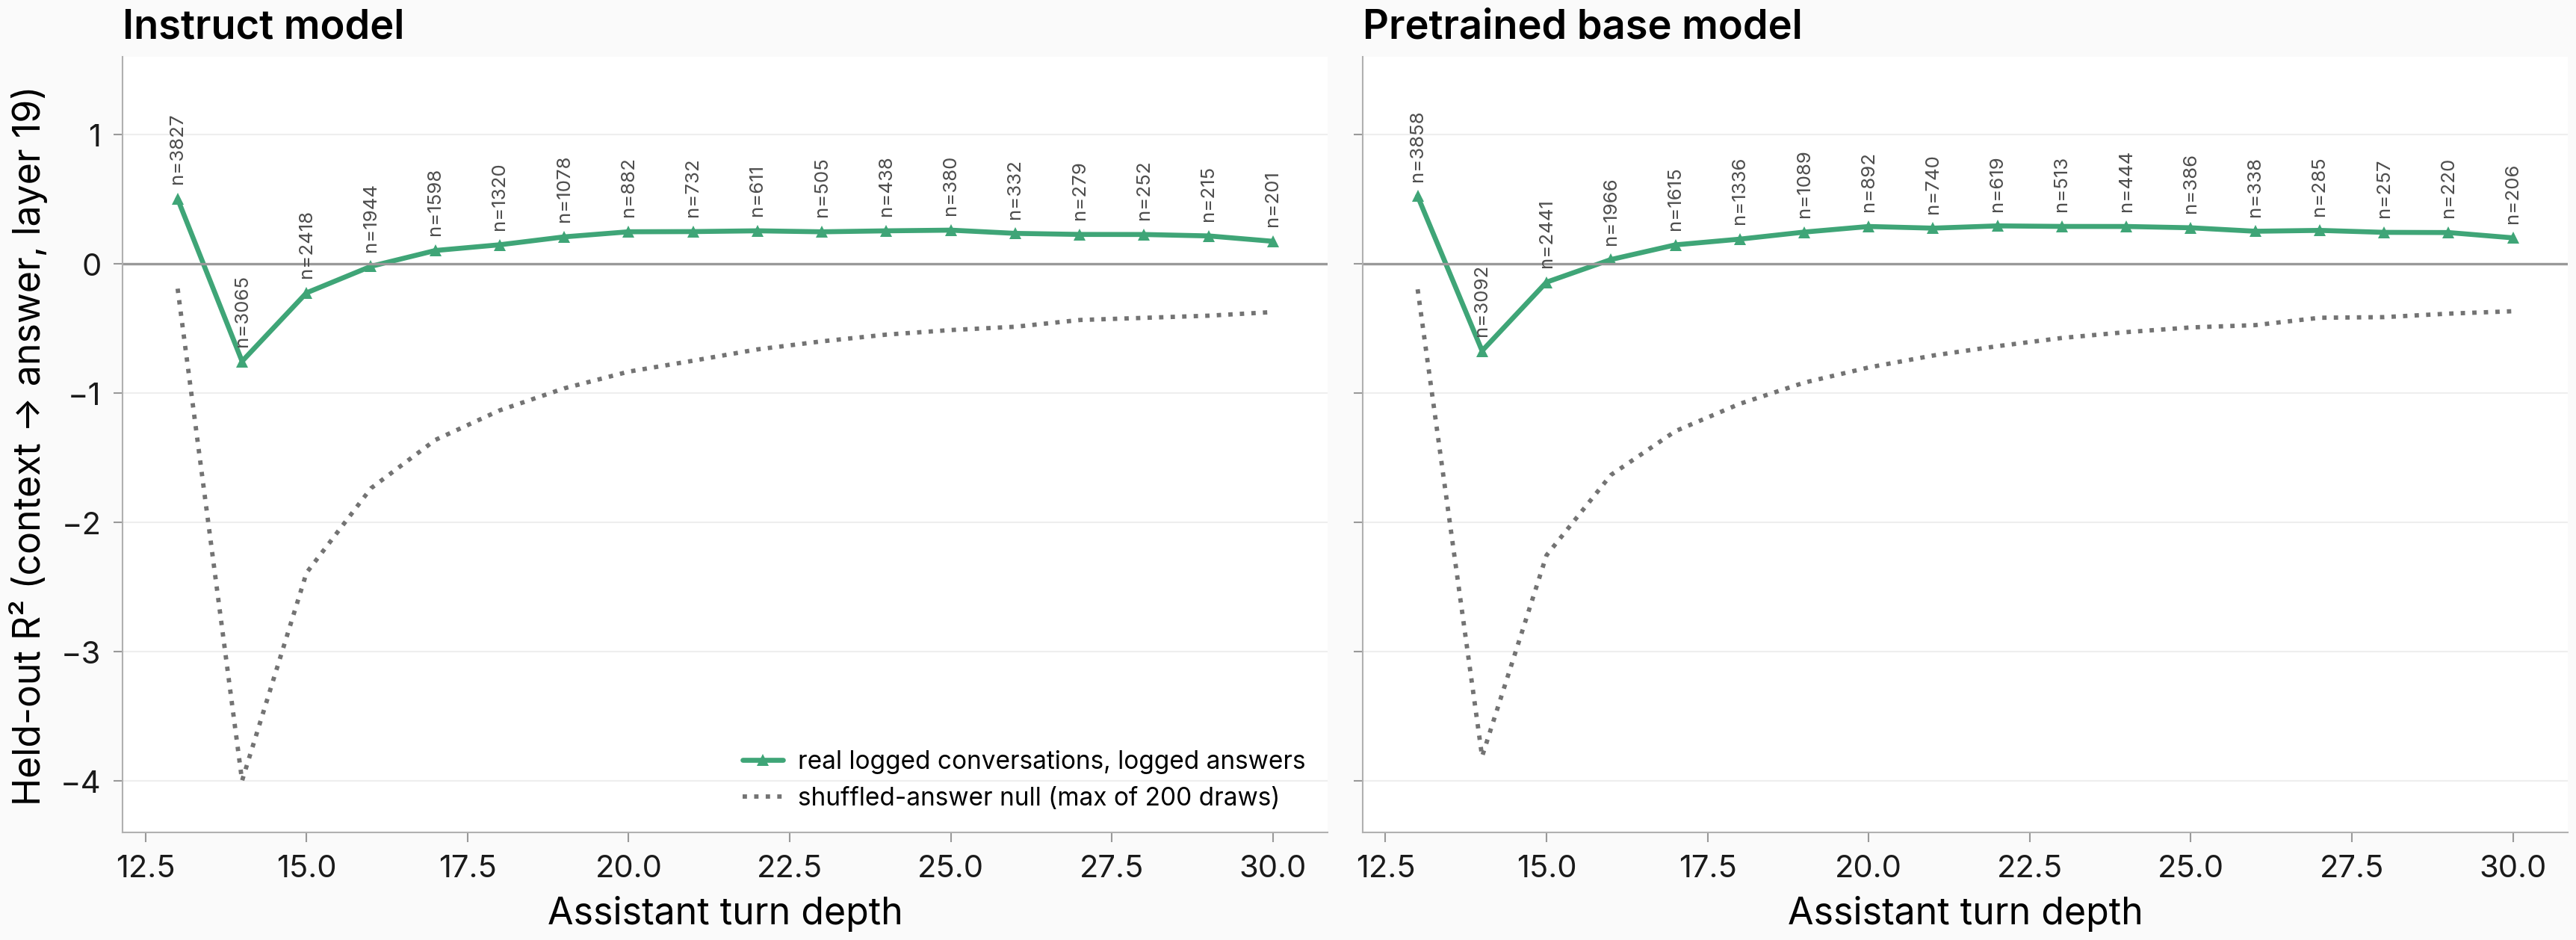
- The real logged tail past the flat panel stays above its shuffled null at every depth to turn 30 (and to turn 48 at n≈31) but breaks regime at turns 14–16 — fold-centered dips negative (−0.755 at turn 14, n=3,065) while the null simultaneously collapses to ≈ −4, an answer-heterogeneity signature — then restabilizes at 0.10–0.29 from turn 17 (fitted-cell n≈1,600→201; exploratory past turn ~23 where n ≤ 500): logged-tail figure
- Caveats: one generation draw and one fit seed throughout; the simulated user turns are third-party-LLM-written (a named tier-3 construction); nulls at layer 19 only (layers 14/18 committed without nulls, same shape, L19 highest); the base turn-1 cell (0.344) sits below Result 1's 0.588 single-turn base anchor — panel composition differs (deep-conversation first turns vs the curated single-turn set), unattributed
Result 8: From turn ~3 on it is ONE shared map — the turn-1 map is genuinely different
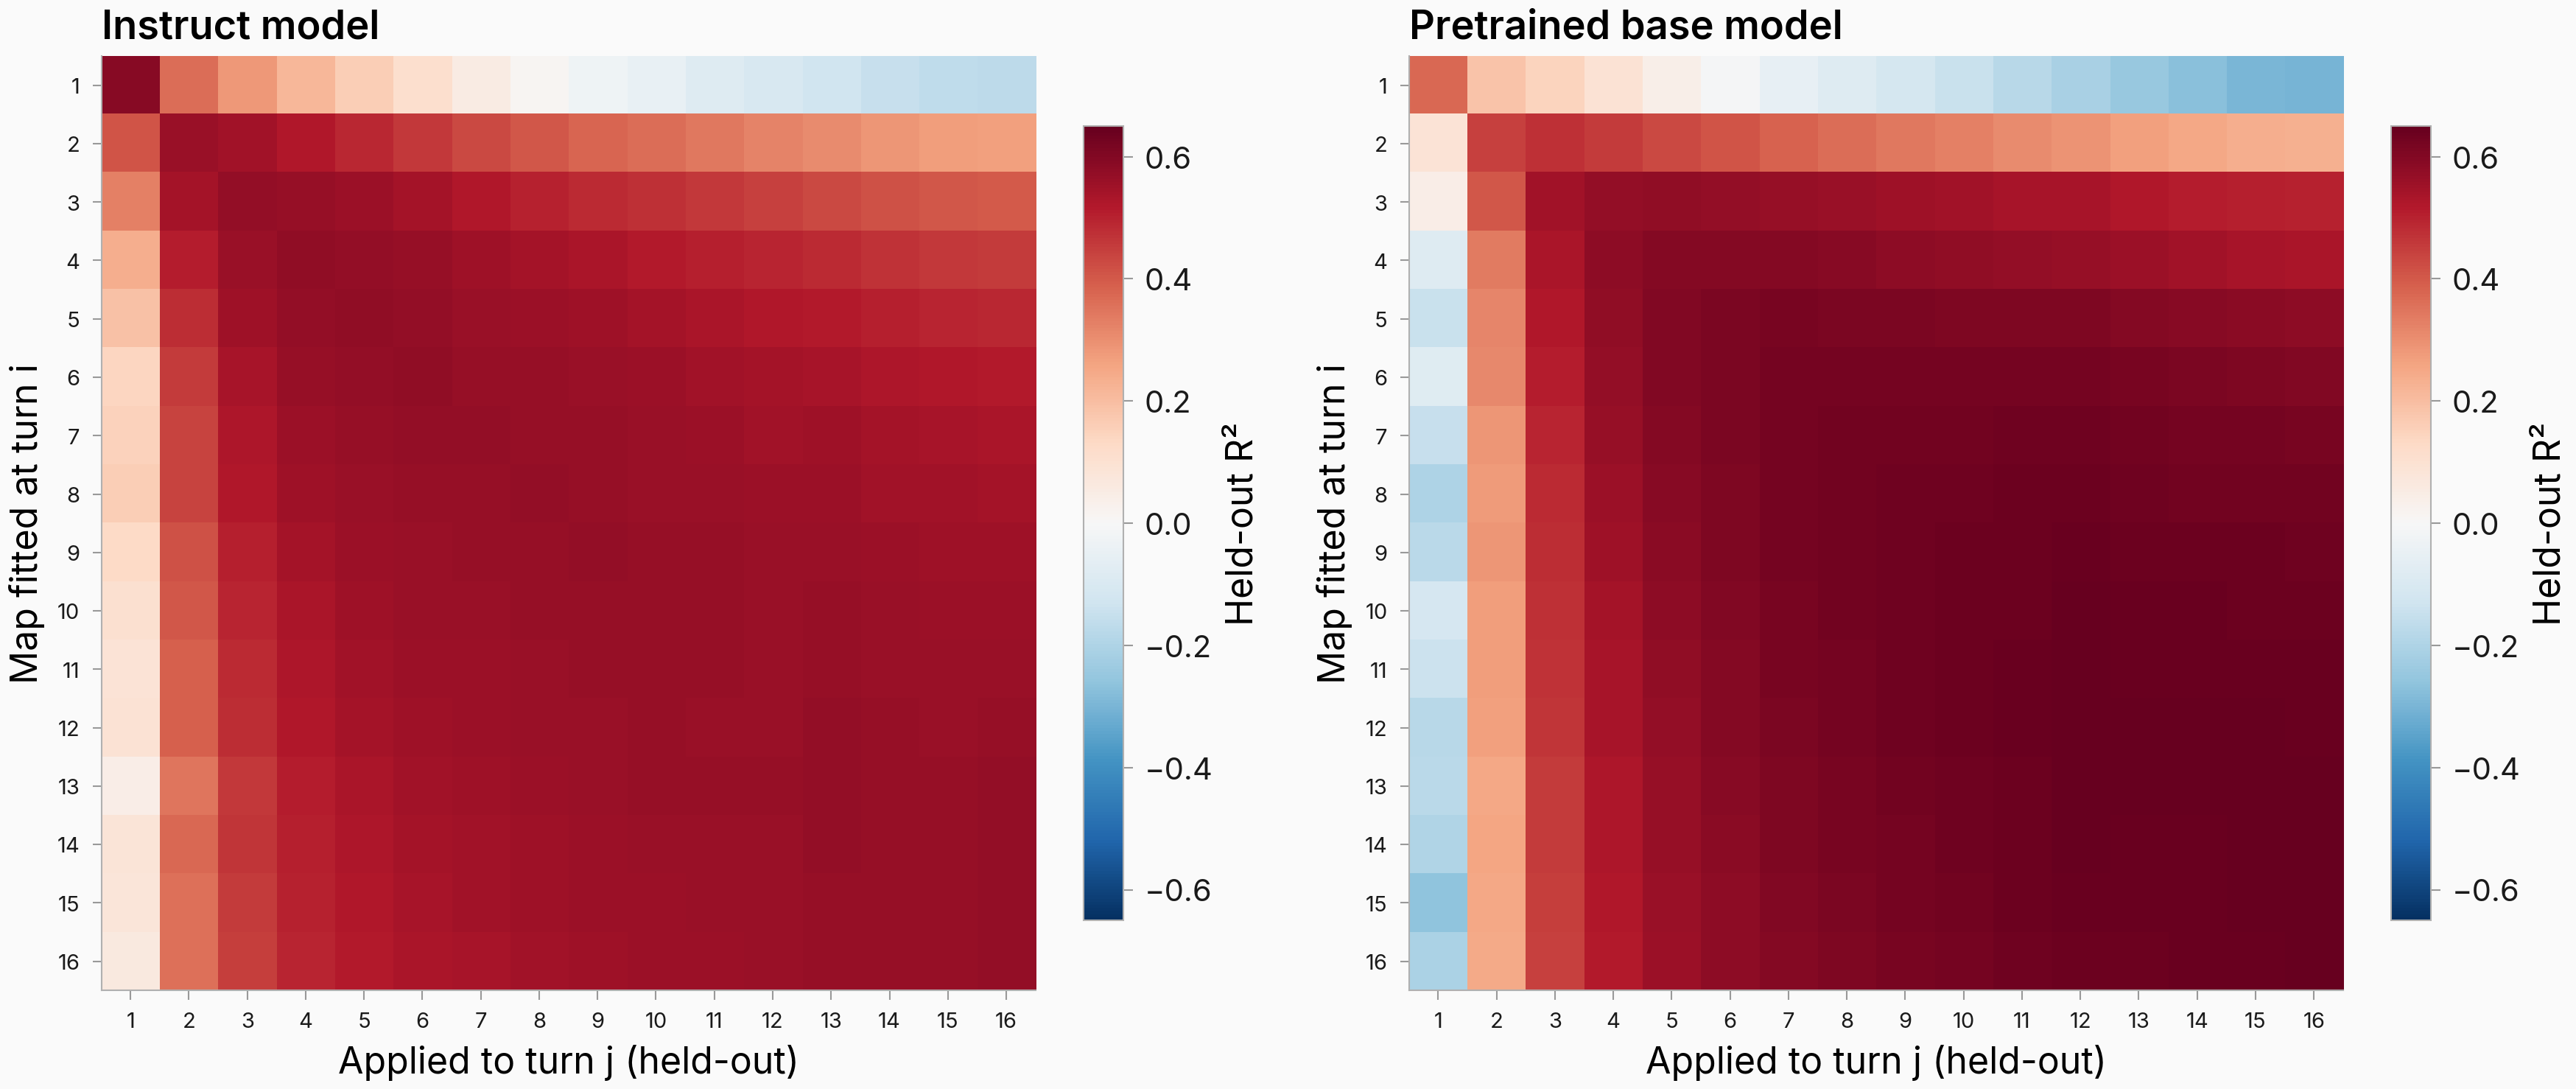
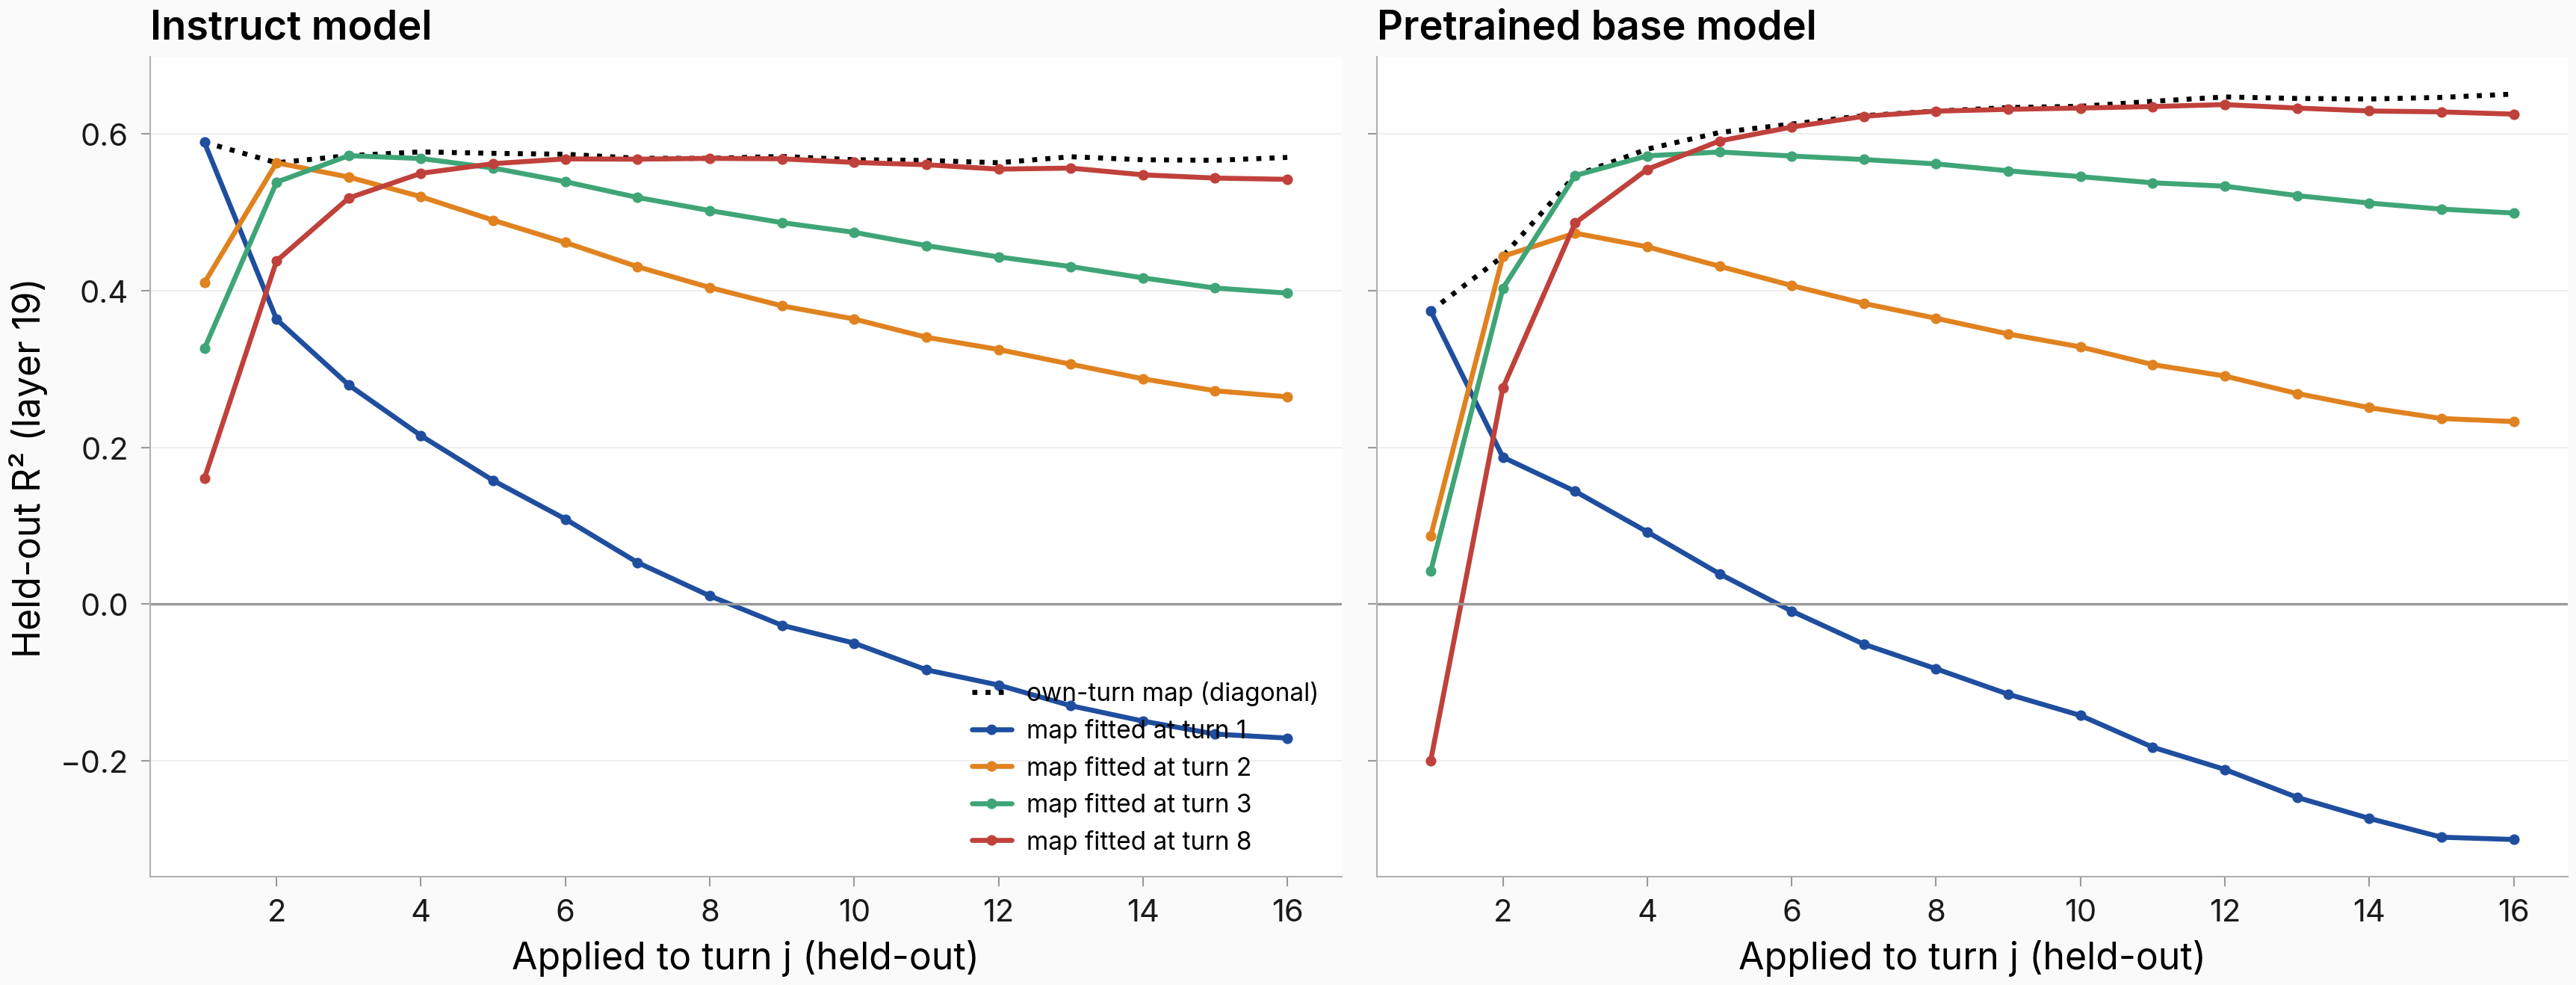
I then asked whether the per-turn maps are the SAME map: fit the map at turn i, apply it to held-out data at turn j (all i×j), compare the operators directly, and fit one pooled all-turns map.
Methodology (this result):
- Simulated-continuation arm (same data as Result 7; n=5,000/turn, turns 1–16, own answers)
- Transfer: the frozen turn-i map scores turn j's held-out folds (shared fold map); shuffled null per target turn
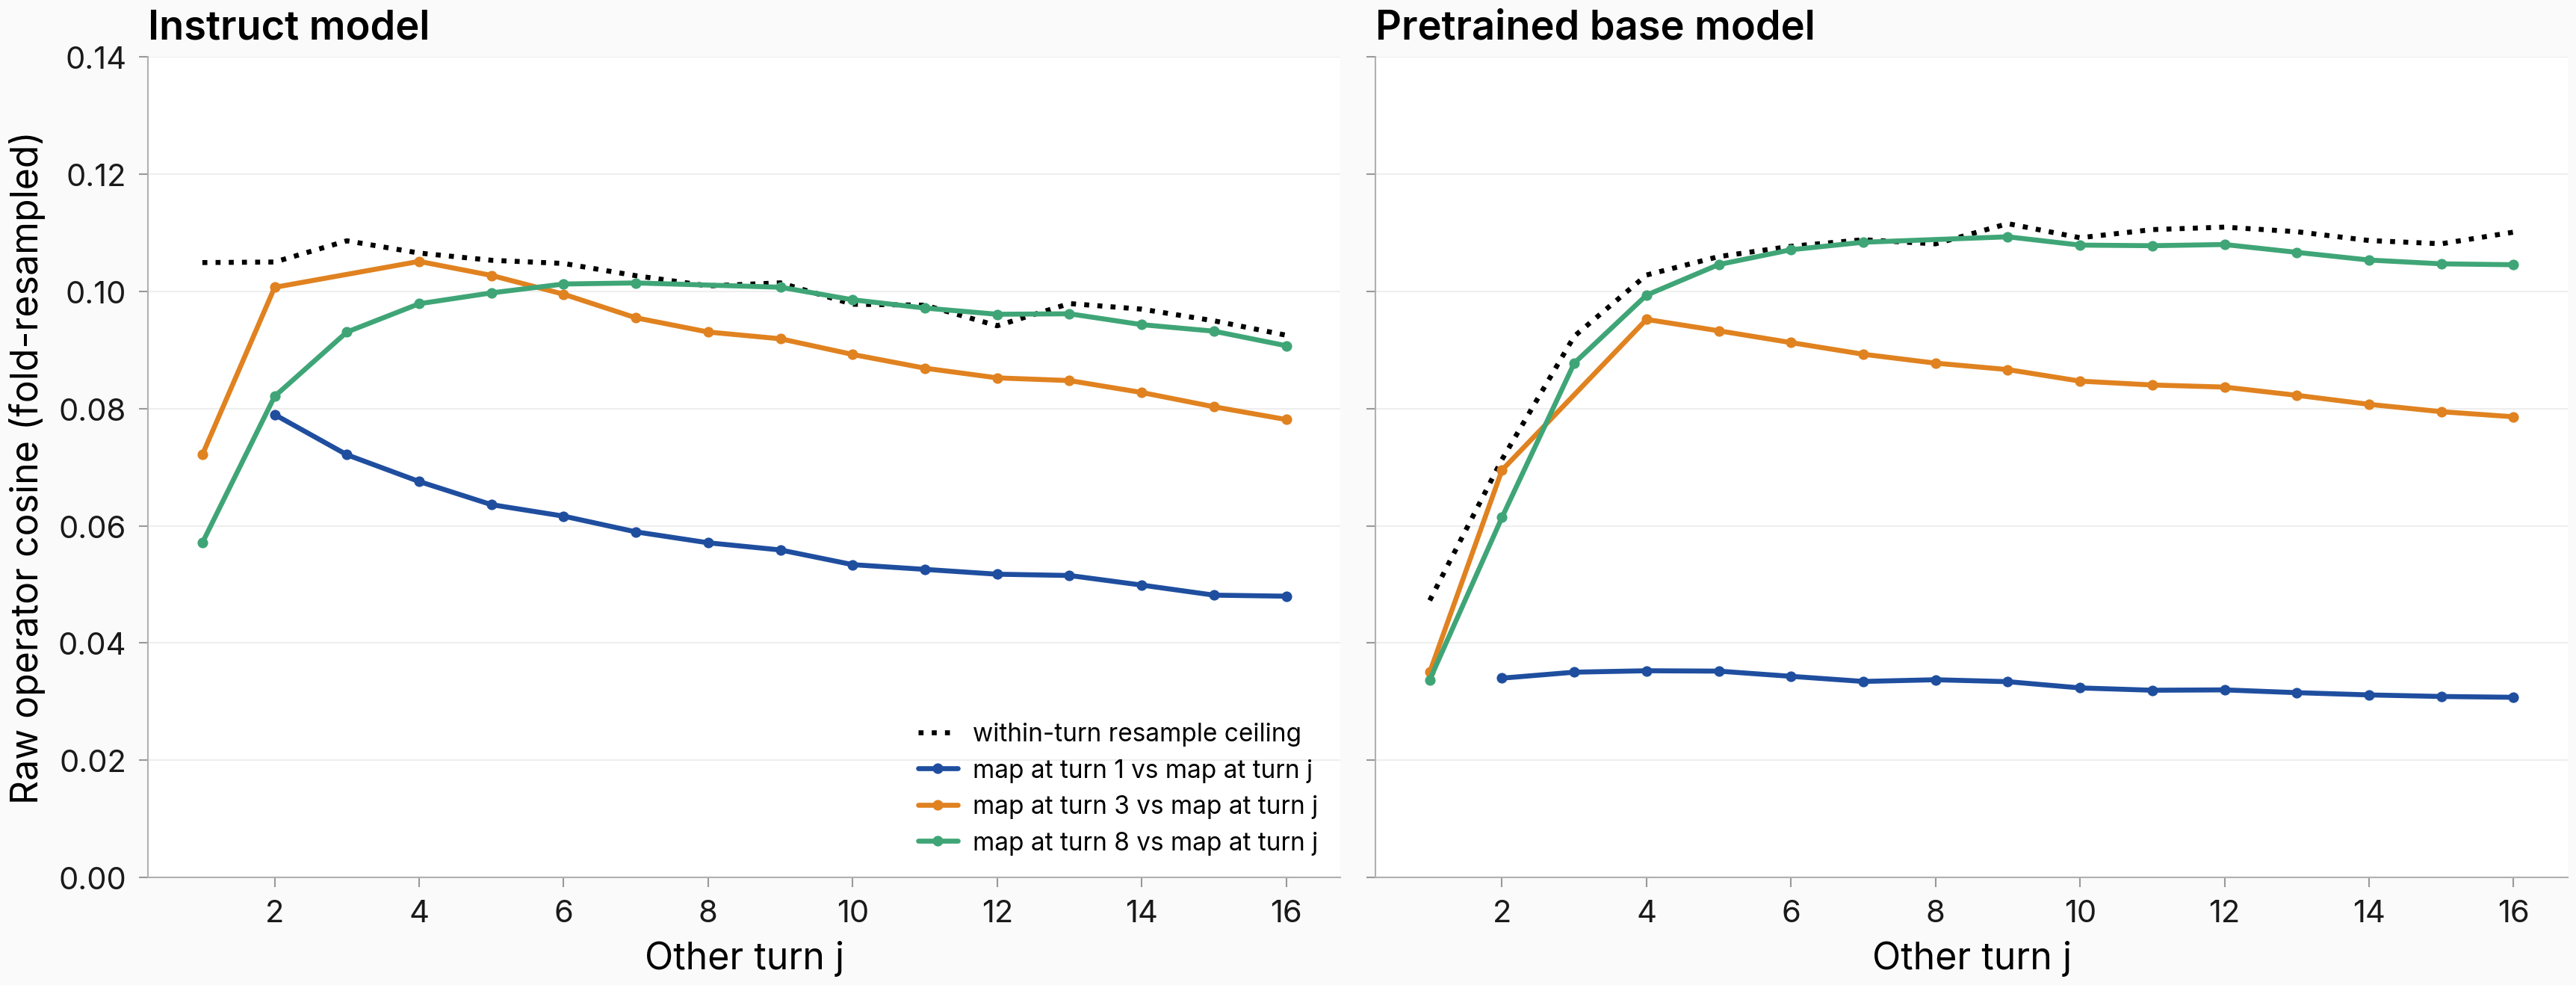
- Operator similarity: raw / Procrustes / general-linear cosine between fold-resampled operators, benchmarked against the within-turn resample ceiling (how similar two resamples of the SAME turn's map are)
- Pooled: one map over all 80,000 (conversation, turn) rows vs the 16 per-turn maps
Takeaways:
- Maps fitted at turns ≥3 are interchangeable: turn i's map keeps ~95% of own-turn on average at any turn j ≥ 3 (min 70–77%), and their operator-space similarity sits AT the within-turn resample ceiling for adjacent pairs (raw cosine 0.09–0.105 vs ceiling 0.10–0.11; distant pairs drift down to 0.078) — statistically the same map: operator-similarity figure
- The turn-1 map is different: applied forward it keeps 65%/42% (instruct/base) at turn 2 and goes NEGATIVE by turn 9/6; later maps applied back to turn 1 collapse (instruct ≤0.33 vs 0.59 own-turn; base ≤0.04). Turn 2 is transitional
- The pooled all-turns map ( 0.645 instruct / 0.650 base) beats the mean per-turn map (0.571 / 0.594) — an earlier in-chat pooled read of ≈ −0.45 does not reproduce at scale; no Simpson-type inversion
- So "how does the map change with depth": it re-parameterizes over the first ~2 turns and then stays put — the change is a property of conversation onset, not of depth
Result 9: The turn-1 context predicts later answers linearly with smooth decay — no nonlinear advantage under this round's probe
I then re-asked Result 5's question with adequate power: how far ahead does the turn-1 context reach, linearly and nonlinearly?
Methodology (this result):
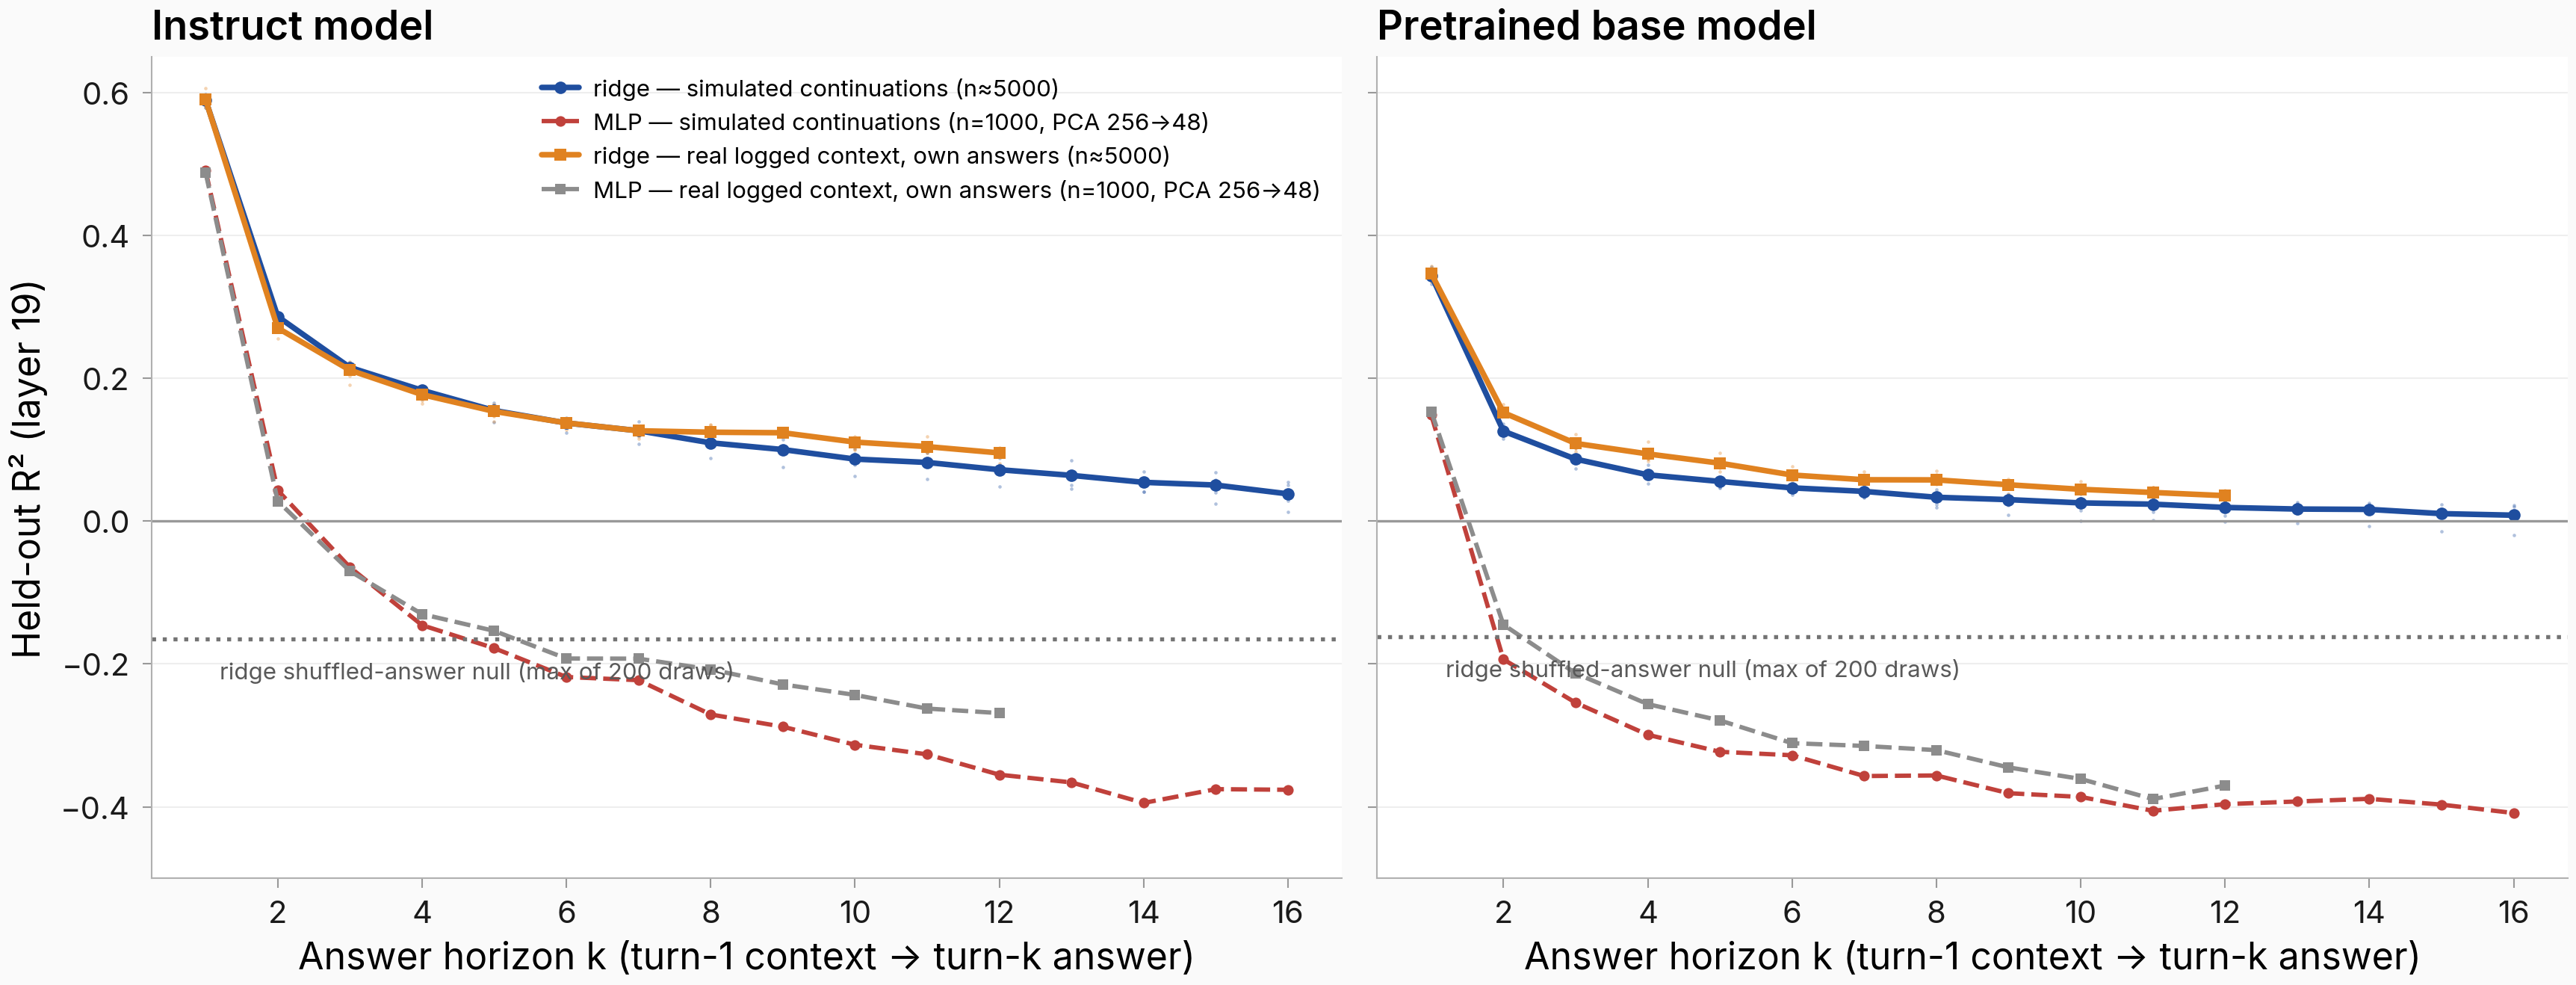
- Fit turn-1 context vector → turn-k answer vector, k = 1..16 (simulated arm) and 1..12 (real arm, own answers); provenance as in Result 7
- Ridge at n=5,000; MLP at n=1,000 (stratified subsample, PCA-256 input → PCA-48 target — matched across horizons within this round, but a different recipe from Result 5's full-dimension-input probe)
Takeaways:
- Linear reach decays smoothly and stays above the shuffled null through k=16: instruct 0.29 (k=2) → 0.18 (k=4) → 0.11 (k=8) → 0.04 (k=16); base 0.13 → 0.07 → 0.03 → 0.01 (near zero by k=16 but still outside the null band ≈ −0.17); real and simulated arms agree
- The MLP never beats ridge at any horizon (0.49 vs 0.59 at k=1; ≤0.04 from k=2 on) — no nonlinear advantage under this round's probe
- This supersedes Result 5 on the linear side (estimator-matched, parity-gated, 2.5× the n): there IS a linear two-turn-ahead map. On the nonlinear side the probes differ (Result 5: full-dimension input + PCA-64 target at n=2,000; here: PCA-256 input + PCA-48 target at n=1,000), and this probe underperforms ridge even at k=1 where signal is strong — so treat its levels as lower bounds and the "nonlinearity holds" question as open pending a probe-matched refit
Next Steps
- Reconcile the two MLP probes on the two-turn-ahead cells (Result 5's full-dimension-input probe vs Result 9's PCA-input probe) on the round-11 tensors — adjudicates whether any nonlinear reach advantage survives
- Diagnose the turn-14–16 logged-tail regime break (per-turn answer-norm/variance profiles from the persisted activation store)
- Tie base model mapping -> instruct model mapping to some form of elicitation vs teaching
- i.e. if the mapping in the instruct model can't be reconstructed from the base model's mapping then there must be some additional skills being taught to the instruct model that aren't present in the base model
- could check if doing RLVR changes the base -> instruct mapping more (the model I'm using is too old to have done RLVR)
Methodology: docs/methodology/issue_825.md · gist
Context: Thomas-authored results summary (verbatim from chat, 2026-07-15) saved as the clean result, superseding the analyzer-authored v4 body — preserved at tasks/<status>/825/artifacts/analyzer-clean-result-v4-2026-07-15.md and in git history. Figures SHA-pinned to 43d7a7e3ea (main): #825 figure set, #1310 per-character stories, and the cross-issue summary set figures/summaries/context_answer_map/. Result 3 updated 2026-07-15 by the naturalistic-single-turn same-issue follow-up (verbatim originating prompt: "run it as inline followup as parallelized and vectorized as possible"): the draft template-comparison figure and its placeholder numbers are replaced by the final Track-S refit — data at eval_results/issue_825/naturalistic-single-turn/ (issue-825 branch @ cf2b8a8d34, recovered from GCP attempt att-20260715-072622 after an upload-phase HF 429 crash; fits complete, upload interrupted), round figures SHA-pinned to c3a01240f0 (issue-825 branch), figure script scripts/issue825_naturalistic_s_figures.py. Result 6 added 2026-07-15 by the onpolicy-turn-depth-map same-issue follow-up (verbatim originating prompt: "reerun with on policy answers for the multi-turn"): data at eval_results/issue_825/onpolicy_turn_depth/results.json, round figures SHA-pinned to b610115c89 (issue-825 branch); generation + capture scripts/issue825_onpolicy_turn_depth_gpu.py, fits + figures scripts/issue825_onpolicy_turn_depth_fit.py; reused #1092 banked context/answer tensors at data-repo revision 9dd650deef (new capture: own-answer spans + prefix positions); registered decision read: provenance contributes (pooled and turn-1 own−logged deltas positive, CIs excluding zero) but turn-1 own-answer R² 0.346 sits below the 0.40 recovery threshold keyed to the 0.476 anchor — remaining gap attributed to the corpus. Results 7–9 added 2026-07-16 by the turn-dynamics-allturns-5000 same-issue follow-up (verbatim originating prompt: "can we run all turns on 5000 samples and check: - if there is a mapping at all turns - how that mapping changes - also if the first context can still predict 2nd turn/3rd turn/4th turn/etc. (linearly and nonlinearly)"): data at eval_results/issue_825/turn_dynamics/results.json (issue-825 branch @ 0df0f8b592, run commit 9ed2930464); round figures + per-cell CSVs SHA-pinned to 968efb6f66 (main), figure script scripts/issue825_turndyn_figures.py; rollout text + activation tensors at HF superkaiba1/explore-persona-space-data under issue825_userbase_map/raw_completions/turn_dynamics/ and issue825_userbase_map/analysis_tensors/turn_dynamics/ (verified via prefix-scoped listing); gates: G-A pass (K_real=12, 5,999 real ≥12-turn conversations), G-B pass (generation depth 16 via the plan's registered fallback ladder; completion 0.92/1.00, role-leak 0), G-C round-10 parity pass both models; bridge H4: instruct within the ±0.10 band at all 12 overlapping turns (max +0.030), pretrained outside at turns 11–12 (+0.104/+0.110).