The own-answer advantage stays outside every probed token-identity subspace up to 32 candidate directions, extending the output-token-commitment falsification from one direction to low-dimensional bundles (HIGH confidence)
Highlight text on any card (body, plan, or an event) to anchor a comment, or leave a whole-task comment here. Mention @claude to summon a reply.
No comments yet.
Methodology: docs/methodology/issue_1072.md · gist
Takeaways
- Token bundles up to 32 candidate directions and the realized next 8 tokens carry 4–10% of the layer-26 own-answer advantage; the complement carries about 90% (all CIs exclude zero).
- Confirmation was reachable this round: the top-32 subspace holds 4.8% of layer-26 target variance where roughly 1.7% sufficed for a rescue — the extended falsification is substantive, not structural.
- The realized-lookahead cell sits marginally below that bound (1.6% variance share), so its falsification is partly structural; the candidate bases carry the family claim.
- Gap enrichment falls with depth and dimension (27× down to 2.0–2.6×), and the bundle gap share stays under the 15% expectation — opposite the commitment prediction.
- The parent result stands: the realized next token's single direction carries 2.4% of the layer-26 gap, and the residual after 16 absorbed answer tokens stays over 95% orthogonal-carried.
Goal
- This experiment in context: The parent run (#952) mapped where the own-answer advantage lives: ridge maps from a context's last-token activation predict the model's activations over its own sampled answer better than over an external answer, the gap growing from 0.009 R² at layer 14 to 0.035 at layer 26, and only 39% of it closing under a 16-answer-token prefix; the grandparent (#823) built the LMSYS pool and answer conditions. This child decomposes every answer-activation target into the realized next token's logit-lens direction plus the orthogonal complement and re-reads the parent's decision statistics per component. Single manipulated factor: the target decomposition; pool, answer conditions, layers, folds, estimator inherited unchanged. A same-issue follow-up round widened the projection basis from the single realized-token direction to three low-dimensional token subspaces (top-8 and top-32 next-token candidates; the realized 8-token lookahead) at layers 14 and 26, testing the natural rescue that output-token commitment is low-dimensional rather than one direction.
- Broader narrative: This serves the context-geometry question of what linear context-to-answer predictability measures. Were the late band output-token commitment, downstream predictors should read mid-band layers for content and treat late layers as decoding-contaminated; the falsification keeps the late band a distributed-content read.
Methodology
Design: Analysis-only diagnostic on frozen Qwen/Qwen2.5-7B-Instruct — no model training; one teacher-forced re-capture pass over frozen completions, a component ridge battery on GPU, then a CPU statistics phase. The inherited measurement, written out as the present method: 4,920 single-turn real-user contexts (LMSYS-Chat-1M prompts; 5,000 sampled, 78 excluded for empty external answers) each carry four frozen answer conditions — the model's own sampled answer (vLLM, temperature 1.0, seed 42), a plain external answer and a distinct-style external answer (both Claude-written), and a deranged mismatched answer as floor. Teacher-forcing each (context, answer) pair through the frozen model yields per-position activations at layers 14/20/23/26; ridge maps predict answer-position targets from the activation at the last context token, and the own-vs-external R² gap on the mean remainder target (mean over answer positions 17 to span end) is the advantage under study. This run decomposes each per-position target into the 1-D component along û = normalize(γ ⊙ W_U[y_next]) — the final-RMSNorm-γ-folded unembedding direction of the realized next token, exact for directions under RMSNorm — and the 3,583-dimensional orthogonal complement, then re-fits the identical battery per component at the λ frozen from the corresponding full-target cell. Both mapping sources are computed: the context-based map (last context token) is primary; the prefix-based map (last token of the pre-user-query prefix) is degenerate by construction on this single-turn pool — the rendered 24-token prefix is constant across contexts — and is reported, not skipped.
Follow-up round (lowdim-token-subspace, run 2026-07-18): the identical battery re-run with the 1-D projection replaced by a per-position token subspace — the top-8 or top-32 next-token candidates by model logit at each position (one added logits pass), or the realized next 8 tokens (order-preserving dedupe, effective size recorded) — each orthonormalized per (context, position) by batched QR over the γ-folded unembedding directions; layers restricted to the endpoints 14 and 26 (a stated cost bound: the four-point depth profile narrows to its endpoints); pool, conditions, folds, estimator, and λ (frozen from the corresponding full-target cells) unchanged. Verdicts per basis via D at layer 26 under Holm correction across the three-cell family; the parent 1-D result rides as the one-direction reference.
Scope: single model, single pool. The construct is representation-level by design (linear-map predictability of frozen answer text), never on-policy behavior prediction; no text is generated anywhere in the run, so no language-intrusion or judge instrument applies. The logit-lens basis is least faithful at earlier layers — a caveat for the layer-14/20 rows; layer 26, the primary, is where the basis is most faithful and where the falsification is largest. About 7% of test contexts have TF-idf near-duplicates in train (inherited caveat); the decision statistics are paired own-vs-external contrasts on identical contexts, which cancel context-level interpolation effects to first order.
Training: N/A — no model training; teacher-forced re-capture over frozen completions. Analysis constants (every value from the plan's grounding card or the committed run JSONs, none from memory; the follow-up round's values from the amendment plan — plans/plan.md, which now points at the round amendment — and its committed round JSONs):
| Parameter | Value | Source |
|---|---|---|
| Model | Qwen/Qwen2.5-7B-Instruct, frozen; bf16 forward, fp16 slot storage | parent rig, inherited |
| Layers | 14, 20, 23, 26 (26 = primary) | task Goal + parent decision layers |
| Projection basis | û = normalize(γ ⊙ W_U[y_next]), γ-folded logit-lens direction of the realized next token | logit lens (nostalgebraist 2020); tuned lens arXiv 2303.08112 |
| Next-token alignment | activation at position p → token at p + 1 | future lens arXiv 2311.04897 |
| Ridge estimator | standardize-X / center-Y, float64 shared-SVD | parent estimator, inherited |
| λ grid | np.logspace(-2, 4, 13), validation-argmax on full-target cells | parent, inherited |
| Component-cell λ | frozen to the corresponding full-target cell's selected λ* | plan rationale (no regularization change rides along) |
| Cross-fit | 5-fold, split rng(952), fold 4 = calibration fold | parent k-fold recipe |
| Capture batch | batch size 8, LEFT padding, bf16, position ids threaded | parent rig |
| Bootstrap | 10,000 multinomial draws, rng 0, fold assignment fixed | parent recipe |
| Sign-flip null | 10,000 draws, rng 1 | parent recipe |
| Multiplicity | Holm step-down over the 3 non-primary layers | parent recipe |
| Pool | 4,920 contexts × 4 answer conditions (19,680 rows); matched population n = 3,188 | parent construction |
| Reduced-range remainder target | mean over answer positions 17 to span end, positions with a realized next token only (rem_mean_gt16_nx) | forced by construction (exact additivity); full-vs-reduced delta reported |
| Additivity tolerance | pooled float64 deviation < 1e-9 (realized max 4.8e-15) | plan success criterion |
| Equivalence gates | recompute-vs-stored cosine > 0.999 per cell | parent gate |
| Parent tensor revision | HF 5b62649cefb34902fd630f21630164e8d1d99764 | reuse pin |
| Completion-set revision | HF 8039d15f30deb845765cbb24d9cdb8708a5e7b0f | reuse pin |
| Subspace bases (follow-up round) | top-8 / top-32 next-token candidate ids per position (one added logits pass); realized lookahead-8 with order-preserving dedupe | followup-scope spec; future lens arXiv 2311.04897 |
| Basis orthonormalization (follow-up round) | batched QR over γ-folded unembedding columns per (context, position); 0 rank-reduced bases (gate) | amendment plan |
| Follow-up layers / multiplicity | 14, 26 (profile endpoints, stated cost bound); Holm step-down over the 3 basis cells | followup-scope marker; parent recipe |
| Follow-up compute | 3.71 GPU-h realized (6 booked), 1× A100-80 | round workload log |
Evaluation: Per (layer, answer condition, cell) the battery stores per-context sufficient statistics; component contributions are C_c = (total SS − residual SS of component c) / total SS of the full target, so R²_full = C_par + C_perp + C_cross exactly. The dependent variables: the gap decomposition ΔC_c (own minus plain external, per component); the parallel gap share S_par = ΔC_par / ΔR²_full; and the decision statistic D = ΔC_par − ΔC_perp at layer 26. Verdict rule: Confirmed iff D > 0 with the 95% CI excluding zero; Falsified iff the CI is wholly below zero; Inconclusive otherwise. The two branches are a priori asymmetric: with the parallel variance share w_par ≪ ΔR²_full, C_par is bounded near w_par, so confirmation would have required the 1-D direction to out-carry the 3,583-D complement; the observed rejection is nonetheless a reachable opposite-tail rejection — D sits 4.6 times outside the sign-flip null band. The closure read repeats the decomposition on the residual leg (the same maps additionally conditioned on the activation at answer position 16), giving per-component closure fractions; these are ratios of pooled sums — the residual-leg channels are pooled-only, so the closure read carries no per-context view (per-context ratios of near-zero sums are unstable by construction). All intervals are pooled bootstrap CIs (10,000 multinomial draws over matched contexts, rng 0) computed with the fold assignment held fixed, so every interval is conditional on that fold assignment; cross-layer and cross-component differences reuse the same draws per resample and are therefore paired.
Validity gates, all passing: span alignment between re-tokenized texts and stored spans — 0 mismatches over all 19,680 rows; recompute-vs-stored slot equivalence — 0 of 3,499,296 (context, slot, layer, condition) cells below cosine 0.999 (minimum 0.9999996); remainder-target channel additivity asserted in-process; full-target reproduction — all 20 (fold × layer) full-target cells match the parent's committed k-fold statistics within 1e-6 with 0 λ mismatches; fold-hash identity asserted on both the GPU and VM sides; bootstrap parity re-check over 200 draws, max abs diff 0.0. In-run pilots: capture projected 0.62 h against 4 h booked; battery 3.63 h against 4 h booked.
Follow-up-round validity gates, all passing: span re-render 0 mismatches over 19,680 rows; recompute-vs-stored slot equivalence 0 of 1,788,866 cells below cosine 0.999 (minimum 0.99966); cross-pass drift on the re-captured remainder target minimum cosine 0.9999995 against a 0.9999 bar; full-target reproduction 525 cells per (fold, layer) within 1e-6 of the completed round with zero λ mismatches; basis rank guard 0 reduced positions; pooled additivity 4.8e-15; bootstrap parity max abs diff 0.0 over 200 draws. Round pilots: capture projected 1.56 h against 1.5 booked (abort bar 3.0); battery 2.08 h against 3.5 booked. An independent re-derivation of every pooled D from the committed per-context channels reproduced the stored values exactly.
Robustness and control reads, all planned cells present: the distinct-style external condition gives D negative at every layer with all CIs below zero, though non-monotone in depth (−0.0143, −0.0412, −0.0313, −0.0368 at layers 14/20/23/26; layer 20 most negative); the mismatched-answer floor stays negative (pooled remainder full R² −0.069 on the matched pool at layer 26), so the maps do not predict generic text statistics; the λ sensitivity sweep has D < 0 at all 13 grid values (−0.024 at the frozen λ* = 3162 down to −0.367 at λ = 0.01); the prefix-based map is degenerate as predicted (full-target test R² −0.016 to −0.020 across conditions at layer 26; max prefix-activation L2 drift 0.97–8.18 by layer, bf16 batch-composition numerics scale); the reduced-range remainder twin differs from the parent's full-range target by at most 0.0016 R² (own condition, calibration fold, layer 26 — about 5% of the gap; the child's full gap 0.0339 matches the parent's 0.0346 endpoint); raw-vs-folded basis cosine over 87,597 unique realized next tokens — mean 0.976, median 0.980, 1st percentile 0.912, minimum 0.689, so γ-folding is a modest rotation. Two template positions were handled as planned: the second-to-last answer position flagged (template-trivial newline next token) and the final position excluded (no realized next token). The enrichment, concordance, per-slot, and paired-layer-difference reads are unadjudicated supplements computed with the same bootstrap recipe and committed alongside the primary statistics.
Follow-up-round robustness and control reads, all planned cells present: under the distinct-style external, D stays negative at layer 26 for all three bases (−0.030, −0.025, −0.031) with the top-32 gap share reaching 20.4% — larger than under the plain external but still a minority; the λ sweep keeps D negative at all 13 grid values per basis (calibration fold, −0.35 to −0.02); the round's re-fit prefix-arm cells stay degenerate as predicted (pooled full-target test R² −0.016 to −0.020 across conditions at layer 26, identical across the three bases); the mismatch-floor companions, re-fit per basis, hold at the parent floor (remainder full R² −0.069, mean over folds, at layer 26); the candidate sets contain the realized next token at 98.3% (top-8) and 99.6% (top-32) of own-answer positions (92.2% and 96.9% under the plain external), so the candidate falsification subsumes the realized direction; lookahead windows share on average 2.0 of 8 tokens with the position's top-32 candidate set and keep all 8 distinct tokens at 81.2% of positions, with 0 rank-reduced bases after dedupe — the lookahead basis is mostly distinct from the current position's candidate set, not an echo of it; the interference check did not fire (|ΔC_cross| at most 0.0026 at a decision cell, an order below ΔC_perp), though for the lookahead basis the cross term (0.0026) exceeds its own parallel term (0.0015); closure at layer 26 repeats the parent's shape per basis (the in-bundle part closes 14–20% vs 36–40% outside); layer-14 D stays negative for all three bases (−0.0074, −0.0068, −0.0071; Holm-corrected p = 0.028), with the depth profile now read at its endpoints only (layers 14 and 26) — a scope narrowing of this round.
Data extraction: Tier-1 real-world prompts (LMSYS-Chat-1M single-turn user queries, gated dataset) with frozen answer conditions produced as described under Design; all inputs consumed at pinned revisions (parent slot tensors + spans at HF 5b62649…; completion texts at HF 8039d15f…). This run adds one decomposition re-capture store (per-condition accumulator shards plus realized next-token id and position arrays) uploaded under its own HF prefix. The run's evaluation rows are per-context sufficient-statistic channels — 8 per cell: residual and total sums of squares for the parallel, orthogonal, cross, and full components. The follow-up round staged the parent stores from the same pinned revisions and uploaded its own subspace accumulator store plus eval-results mirror under a second HF prefix (issue1072_lowdim_token_subspace/).
Sample training/evaluation data + completions: No text is generated or trained on; raw LMSYS text is not reproduced here (the pool carries unscreened real user content — texts resolve at the pinned revisions above). The worked example and spot check below quote the committed per-context channels verbatim.
Worked example — matched context 408, layer 26, mean remainder cell, fold 4, all four answer conditions
1 of 3,188 rows — a random sample (numpy seed 42, the first drawn context of the spot check below); full arrays: per_context_stats_1072_fold4.npz plus folds 0–3 in the same HF directory at the pinned data-repo revision (the .npz are gitignored — HF-only, not in the git tree). Channels are per-context sums of squares (residual | total) per component; derived quantities follow the Evaluation definitions.
| answer condition | res par | tot par | res perp | tot perp | res full | tot full | R² full | c_par | c_perp | c_cross |
|---|---|---|---|---|---|---|---|---|---|---|
| own answer | 36.2 | 51.7 | 13,220.4 | 15,855.8 | 13,515.8 | 16,219.6 | 0.167 | 0.00095 | 0.16249 | 0.00326 |
| external answer (plain) | 19.6 | 28.1 | 10,094.1 | 12,409.7 | 10,340.6 | 12,717.4 | 0.187 | 0.00067 | 0.18209 | 0.00413 |
| external answer (distinct style) | 17.3 | 17.2 | 8,038.8 | 10,124.4 | 8,180.2 | 10,300.2 | 0.206 | −0.00001 | 0.20248 | 0.00336 |
| mismatched answer (floor) | 264.0 | 215.8 | 21,032.3 | 19,273.7 | 21,413.7 | 19,632.9 | −0.091 | −0.00245 | −0.08957 | 0.00133 |
For this context the own-minus-plain-external full difference is negative (−0.020), illustrating the per-context spread the pooled statistic averages over; additivity c_par + c_perp + c_cross = R²_full holds per row.
Spot check — 5 random matched contexts (seed 42), own answer, layer 26 mean remainder cell
5 of 3,188 rows — a random sample (numpy seed 42) from fold 4; full arrays: per_context_stats_1072_fold4.npz (folds 0–3 alongside), with the raw channel + log mirror at HF issue1072_component_decomposition/eval_results.
| context id | res full | tot full | per-context R² | additivity deviation |
|---|---|---|---|---|
| 408 | 13,515.8 | 16,219.6 | 0.167 | 0 |
| 2082 | 3,758.3 | 11,085.8 | 0.661 | 9.8e-4 (float32) |
| 2095 | 7,983.2 | 13,164.1 | 0.394 | 0 |
| 3114 | 2,012.4 | 16,808.2 | 0.880 | 0 |
| 3795 | 6,048.4 | 11,326.1 | 0.466 | 0 |
Per-row additivity holds to float32 precision; the pooled float64 additivity deviation is at most 4.8e-15 (tolerance 1e-9).
Results
The own-answer advantage is orthogonal-carried at every probed layer, and the deficit grows with depth
What is plotted: the own-minus-plain-external gap in mean-remainder R², stacked into parallel, orthogonal, and cross parts per layer, with D and its 95% CI below; n = 3,188 matched contexts.

Figure. The orthogonal complement carries the gap at every layer. Stacked contributions of the own-vs-plain-external gap (mean remainder target); diamonds:
D=ΔC_par−ΔC_perp(parallel-minus-orthogonal gap difference) with 95% bootstrap CI. Layer 26:D= −0.031, CI [−0.038, −0.025]; sign-flip null band [−0.0068, +0.0067].
| layer | ΔC_par | ΔC_perp | ΔC_cross | ΔR²_full | S_par (95% CI) | D (95% CI) | Holm-corrected p |
|---|---|---|---|---|---|---|---|
| 14 | 0.00013 | 0.00797 | 0.00008 | 0.00817 | 0.015 [0.009, 0.047] | −0.0078 [−0.0135, −0.0022] | 0.0059 |
| 20 | 0.00031 | 0.01789 | 0.00023 | 0.01844 | 0.017 [0.013, 0.024] | −0.0176 [−0.0233, −0.0120] | 0.0003 |
| 23 | 0.00062 | 0.02237 | 0.00029 | 0.02328 | 0.027 [0.021, 0.035] | −0.0218 [−0.0274, −0.0163] | 0.0003 |
| 26 | 0.00081 | 0.03223 | 0.00086 | 0.03390 | 0.024 [0.019, 0.030] | −0.0314 [−0.0381, −0.0249] | primary layer |
The falsification rule fired at every probed layer: the token direction carries 2.4% of the layer-26 gap, the complement 95.1%, and D sits 4.6 times outside the sign-flip null band. The two verdict branches are a priori asymmetric (Evaluation note), so the informative quantities are the gap share and the enrichment trend, not the sign alone.
Stable across both external conditions, all 13 ridge penalties, all 5 folds.
The unclosed layer-26 residual is also orthogonal-carried; the parallel sliver resists absorption but is negligible
What is plotted: the layer-26 own-vs-plain-external gap per component, before and after conditioning on the activation at answer position 16; mean remainder target.
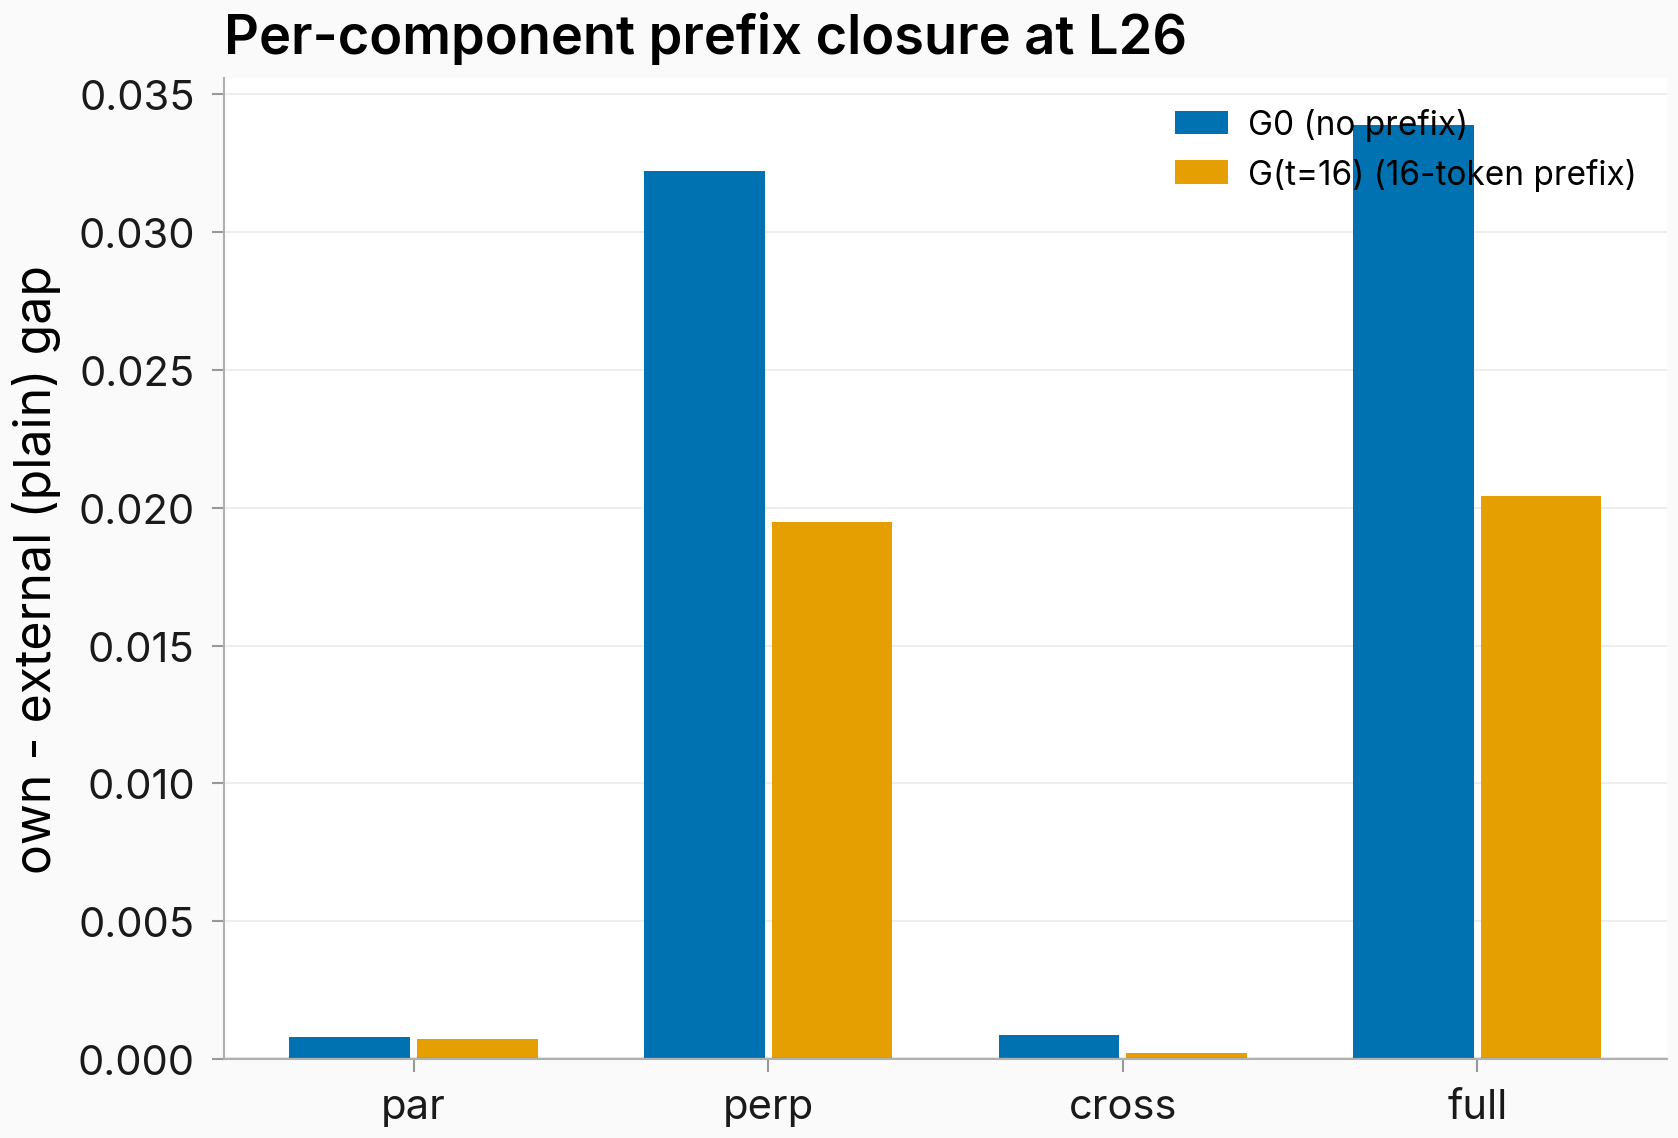
Figure. The unclosed layer-26 residual is orthogonal-carried. Gap per component with no prefix vs after 16 absorbed answer tokens. Residual-leg statistic −0.0188, CI [−0.0265, −0.0111]; closure fractions: parallel 8.8% [0.3%, 16.7%] vs orthogonal 39.5% [17.7%, 60.6%]; unclosed-fraction difference CI [0.109, 0.504].
Of the 0.0339 full gap, 0.0204 survives 16 absorbed answer tokens — again complement-dominated (0.0195 orthogonal vs 0.00074 parallel), the residual-leg statistic negative with its CI excluding zero.
The relative clause holds: the parallel sliver closes at 8.8% against 39.5%, a difference excluding zero. Token-identity information resists prefix absorption where present, but its mass is negligible, so the layer-26 closure stall is not token commitment.
Most matched contexts individually put the gap in the orthogonal complement
What is plotted: per-context paired own-minus-plain-external differences, parallel contribution against orthogonal, at layer 26; one point per matched context, marginal histograms; no aggregation.

Figure. Most contexts individually put the gap in the complement. Per-context paired differences at layer 26 (n = 3,188): 62.1% show a larger orthogonal than parallel difference; medians 0.0224 (orthogonal) vs 0.0004 (parallel).
The unaggregated view behind the layer-26 table row: 62.1% of the 3,188 matched contexts show a larger orthogonal than parallel difference (medians 0.0224 vs 0.0004); the parallel axis spans a far narrower range.
The pooled falsification compresses a broad per-context pattern rather than a few high-leverage contexts.
The token-identity direction is real but small, and its gap enrichment falls with depth
What is plotted: four exploratory panels — parallel gap share by layer; parallel variance share; per-slot contributions over the first 16 positions; raw-vs-folded cosines.

Figure. Variance share rises with depth; gap enrichment falls. Enrichment = gap share over variance share: 27.3 [16.1, 83.8] at layer 14 to 3.9 [3.2, 4.8] at layer 26; paired layer-26-minus-layer-14 difference CI [−79.4, −12.5]. The per-slot panel is single-fold and descriptive — a within-first-16 profile, consistent with the parent's coarse early-vs-late uniformity read.
The depth-profile read (parallel share rising with depth) is unsupported: the paired layer-26-minus-layer-14 change in S_par is +0.0084 with a CI spanning zero. Variance share rises about 10.9-fold, consistent with logit-lens expectations. Enrichment nonetheless falls from 27.3 to 3.9, with its paired difference excluding zero: the opposite depth trend from token commitment.
Per slot, the orthogonal gap concentrates early (0.079 at position 2, falling to 0.010 by position 16) while the parallel part peaks at position 1 and declines monotonically.
Token bundles up to 32 candidate directions also fail to carry the layer-26 advantage, and this time the confirmation branch was reachable
What is plotted: the layer-26 own-minus-plain-external gap split into parallel, orthogonal, and cross parts per basis, with D and its 95% CI, then the per-context top-32 split; n = 3,188.

Figure. No low-dimensional token bundle carries the layer-26 gap. Stacked gap contributions per basis; diamonds:
Dwith 95% bootstrap CI — top-8 −0.029 [−0.035, −0.023], top-32 −0.026 [−0.032, −0.020], lookahead-8 −0.028 [−0.035, −0.022]; Holm-corrected p = 0.0003 each. Gap-share and enrichment profile: companion figure, deliberately linked.


Figure. Per-context view behind the aggregate. Each point is one of the 3,188 matched contexts: own-minus-plain-external gap inside the top-32 candidate subspace vs outside it, layer 26, with marginal histograms; 61.4% of contexts put more of their gap outside the bundle.
All three bundles land on the falsification side. The candidate subspaces hold 2.5% and 4.8% of layer-26 target variance, above the ~1.7% a rescue needed, so confirmation was reachable and the rejection substantive.
The lookahead cell sits marginally below that bound (1.6%), its falsification partly structural. Gap share stays under the 15% expectation — 2.4%, 6.0%, 9.7% for 1, 8, 32 directions — and 61.4% of contexts put more of the gap outside the top-32 bundle.
Repro: 4.17 GPU-h realized (9 booked) on 1× A100-80 (GCP flex-start auto lane): staging + teacher-forced decomposition capture (pilot-projected 0.62 h) + component ridge battery (5 folds, pilot-projected 3.63 h); VM CPU statistics phase ~17 s plus supplementary reads. Code at 1f19deacfd (branch issue-1072): driver run_1072.py, stats issue1072_stats.py, figures issue1072_figures.py, supplementary issue1072_supplementary.py. Artifacts: eval_results/issue_1072/ (11 JSONs: stats_component.json, supplementary_reads.json, battery_1072_fold{0..4}.json, capture_gates.json, stage_manifest.json, pilot gates; the 5 per_context_stats_1072_fold{0..4}.npz are gitignored and live on the HF eval_results mirror only) and figures/issue_1072/ at the same SHA; HF data repo issue1072_component_decomposition/ (40 files, listing re-verified live at write time via list_repo_tree at the pinned revision: analysis_tensors — 25, incl. the 16 decomposed accumulator shards + next-token id and position arrays; eval_results mirror — 14, excluding the 2 VM-computed stats JSONs, which live in git only; logs — 1 workload log). Reused slot tensors + spans from #952: issue952_position_divergence/analysis_tensors/ at revision 5b62649cefb34902fd630f21630164e8d1d99764 — fit: identical pool/conditions/layers from the same capture rig; 59-file listing + shard header re-verified at staging. Reused completion texts from #823: issue823_own_vs_external/raw_completions/ at revision 8039d15f30deb845765cbb24d9cdb8708a5e7b0f — fit: the exact completion set the reused #952 slot tensors index; byte-size assert table re-run at staging and span alignment re-verified in-run (0 mismatches over 19,680 rows). Seeds: fold split rng(952); bootstrap rng 0; sign-flip rng 1. Judge: n/a (no LLM judging anywhere in the run). Same-issue follow-up round lowdim-token-subspace: 3.71 GPU-h realized (6 booked) on 1× A100-80 (GCP auto lane; one crash-fix relaunch — missing base-dir creation before the statvfs headroom probe on a fresh instance, fix 74ea8b8e7e). Round code at 60f0c18004 (branch issue-1072-lowdim; figures regenerated at 2435cd10e4): driver run_1072_lowdim.py, stats issue1072_lowdim_stats.py, figures issue1072_lowdim_figures.py. Round artifacts: eval_results/issue_1072/lowdim-token-subspace/ (10 git-tracked JSONs: stats_lowdim.json, battery_lowdim_fold{0..4}.json, capture_gates_lowdim.json, stage_manifest_lowdim.json, 2 pilot gates; the 5 per_context_stats_lowdim_fold{0..4}.npz live on the HF mirror only) and figures/issue_1072/lowdim-token-subspace/ at 2435cd10e4; HF prefix issue1072_lowdim_token_subspace/ (31 files, listing re-verified live at write time via list_repo_tree: analysis_tensors — 16: the 8 per-arm-per-layer subspace accumulator shards, 4 per-arm manifests, and 4 per-arm top-32 candidate-id arrays; eval_results mirror — 14, incl. the 5 per-context npz; logs — 1 workload log).
Context: created 2026-07-06; run 2026-07-18 (one run round plus one interpretation-revision round, no new compute). Child of #952 (own-answer band-map gradient + closure stall); grandparent #823 (pool + answer conditions). Origin prompt not recorded — autonomously filed, no user prompt; filing provenance, verbatim:
Auto-filed (filed-only, never auto-spawned) from
epm:follow-ups v3proposal 3 on parent #952 at the kfold-decision-cells re-park, after the follow-up-critic + codex-follow-up-critic redundancy screen returned not-redundant x2 (epm:followup-value-critique v3 + epm:followup-value-critique-codex v3).
Same-issue follow-up round lowdim-token-subspace run 2026-07-18 (proposer-initiated cheap-band auto-run; epm:followup-scope v1 posted 2026-07-18, source: proposer-9b-cheap, est_gpu_hours: 4, headline_affecting: yes; no user prompt). Round spec, verbatim from the scope marker's Differs from parent field:
Exactly one thing — the projection basis: the 1-D realized-next-token direction becomes a panel of low-D γ-folded unembedding subspaces (3 levels of the same factor): span of the model's top-k predicted next-token candidates at each position (k ∈ {8, 32}; candidate ids from one light forward pass dumping top-32 logit ids per position — logits are not in the store) and span of the realized next 8 tokens' directions (lookahead; ids re-derived from stored spans + the pinned #823 completion texts, span alignment already verified 0/19,680 mismatches). Layers restricted to 14 and 26 (the trend endpoints) to bound cost.